# The Adpharm — Insights
Full content of every published post. Frontmatter included for citation purposes.
Source: https://www.theadpharm.com/insights
---
## Results: 60 days after making a vet clinic citable by AI
URL: https://www.theadpharm.com/insights/sixteen-mile-vet-ai-answer-engine-seo-results
Source markdown: https://www.theadpharm.com/insights/sixteen-mile-vet-ai-answer-engine-seo-results.md
Published: 2026-07-09
Category: case-studies
Author: adpharm-digital
Reviewed by: ben-honda
Tags: ai-eo, technical-seo, case-study, ai-citations, generative-engine-optimization, core-web-vitals
> TL;DR: Sixty days after the [AI-EO pass on sixteenmilevet.com](/insights/sixteen-mile-vet-ai-answer-engine-seo), first-party citation rate across ChatGPT, Claude, and Google AI rose from 29% to 38%, the informational blog posts that were invisible on day 0 now get cited by name, human visitors tripled while crawler and AI-bot traffic jumped roughly 14×, and Bing's AI Performance report logged 1,544 citations with a 6.5× ramp across the window. The "best vet in Oakville" query and Powassan are the laggards.
This is the measured follow-up to [Making a vet clinic citable by ChatGPT, Perplexity, and Claude](/insights/sixteen-mile-vet-ai-answer-engine-seo), which covers what we shipped and why. Here we report what sixty days of crawl-and-cite actually produced.
Start with who showed up, measured in [Silo CDP](/products/silo). First the people searching — the 61 days before launch laid over the 61 days after, day for day. Then the machines, over that same post-launch stretch, broken out by crawler.


Both run on the same clock. The human lines track together for five weeks, then the post-launch line pulls away in mid-June. The crawlers do the same — near-silent until mid-June, then a Googlebot re-crawl and ByteDance's Bytespider pour in, everything else stacked behind them. That timing, five to six weeks after launch, is exactly when Google re-indexed the site and Bing's AI citations started climbing.
> [!aside] What happened around day 40?
>
> Launch was day 0, but nothing moved for five weeks — because getting cited by AI is a chain, not a switch. Google and Bing first had to re-crawl the rebuilt pages (the new robots policy, router-driven sitemap, and `/llms.txt` all point them in), then re-index them, and only then could answer engines retrieve and quote them. That pipeline took roughly five to six weeks to clear, which is why human visitors, crawler hits, indexed-page count, and AI citations all inflect together in mid-June rather than at the May launch. The practical takeaway: AI-EO is a re-crawl story — budget four to eight weeks before the needle moves.
We re-ran the same seven queries through the same three engines (ChatGPT with search, Claude with web search, and Google's AI surface), from a logged-in Canadian session, on day 0 and again at day 60. The queries did not change between runs. "Cited" means the clinic's own domain appears in the engine's citation panel; first-party citation — the clinic's site, not a directory or review aggregator — is the harder bar, and it is the bar every one of these citations clears.
## Headline numbers (day-0 → day-60)
| metric | day-0 (2026-05-09) | day-60 (2026-07-09) | Δ |
|---|---:|---:|---:|
| Cited rate (any) | 29% | 38% | +9 |
| First-party rate | 29% | 38% | +9 |
| Brand-mention rate | 33% | 38% | +5 |
By engine:
| engine | day-0 cited | day-60 cited | Δ |
|---|---:|---:|---:|
| ChatGPT | 3/7 (43%) | 3/7 (43%) | flat |
| Claude | 1/7 (14%) | 2/7 (29%) | +1 |
| Google AI | 2/7 (29%) | 3/7 (43%) | +1 |

## What moved
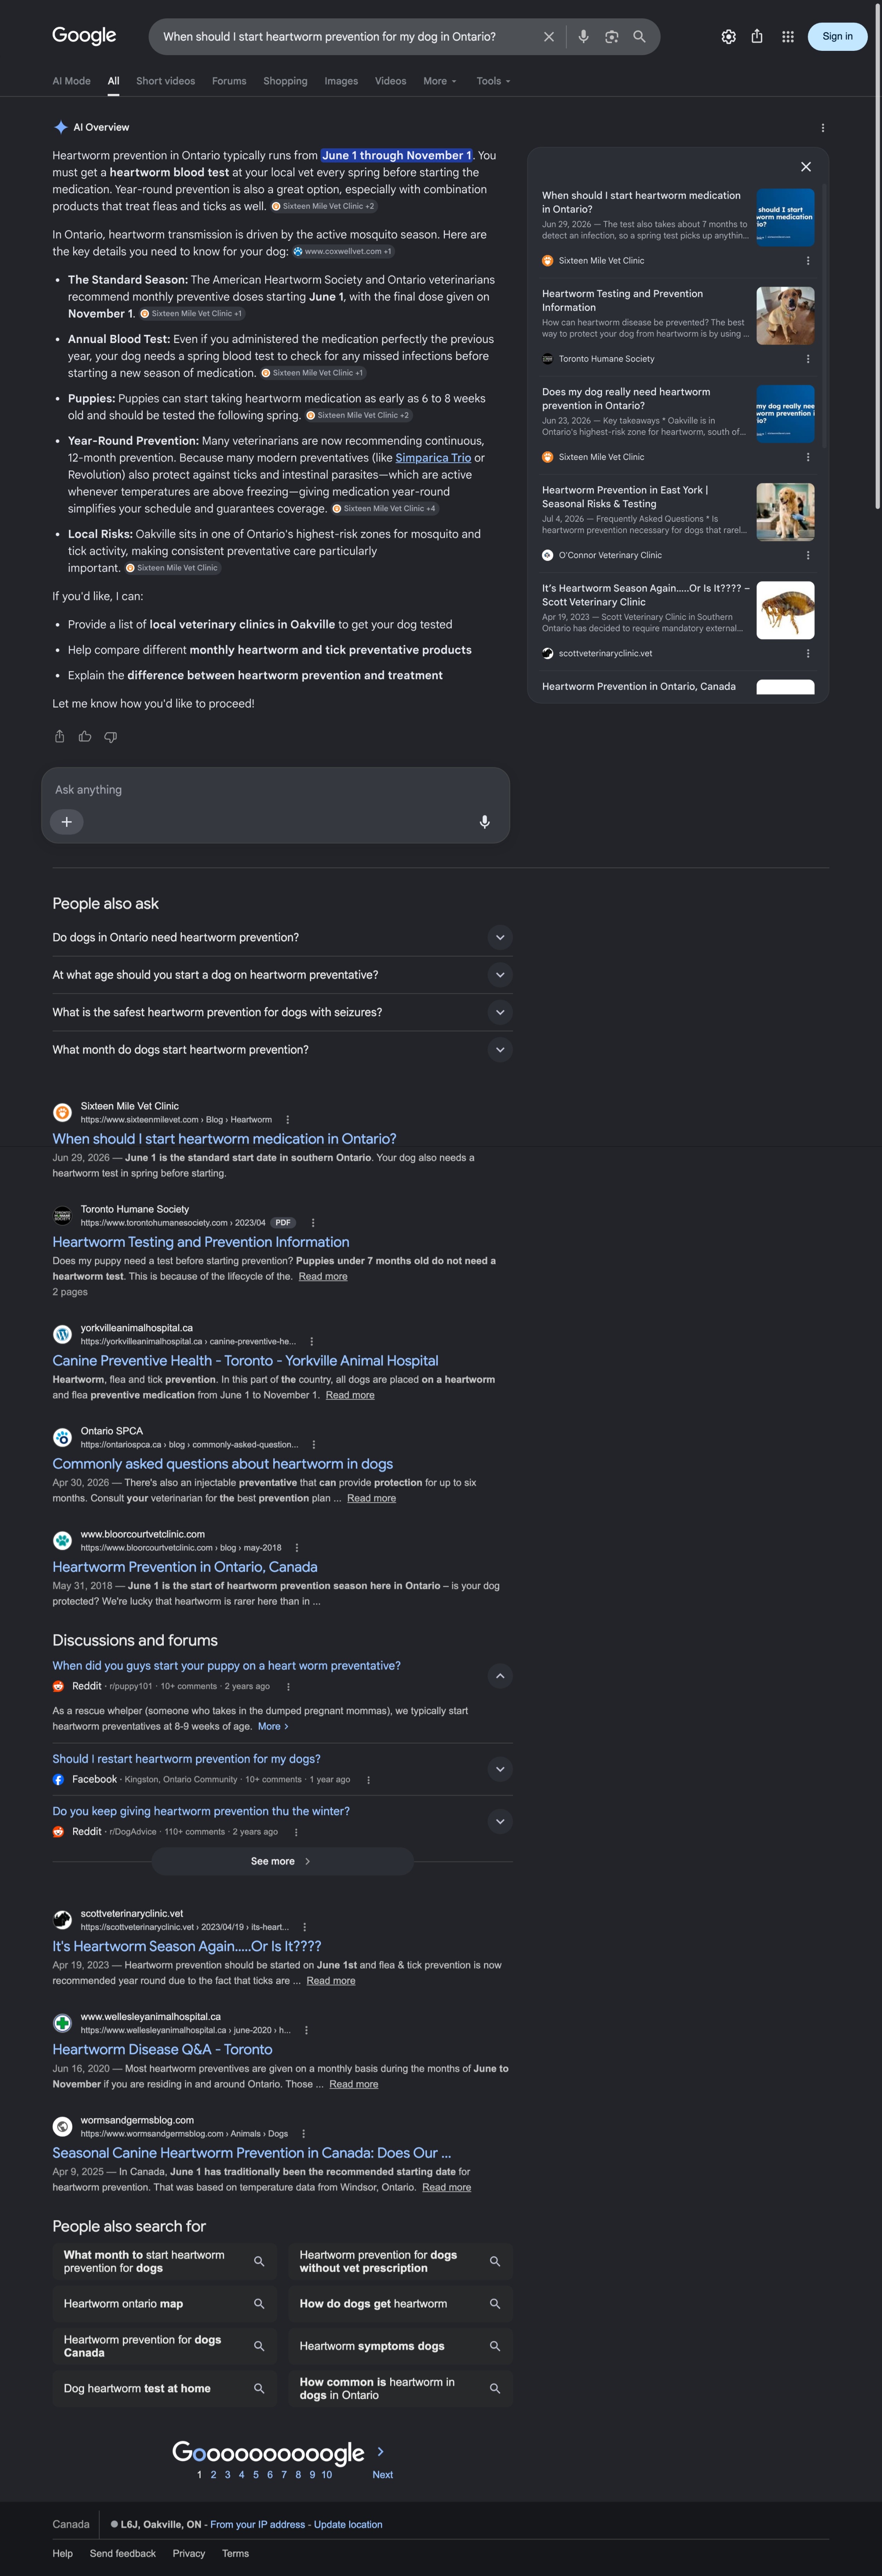
1. **The slug-match informational queries.** Heartworm, ticks, and Powassan — the three queries pointed at specific blog posts — were 0 for 9 across all engines on day 0. This was the load-bearing test: does publishing the answer actually surface the page once it is crawled? At day 60, the heartworm post is cited first-party by both ChatGPT and Google (Google quotes the "June 1 through November 1" window straight from it), and the tick post is cited first-party by Claude and ranks first in Google's organic results. Two of the three landed. Powassan is the holdout and stayed at zero.
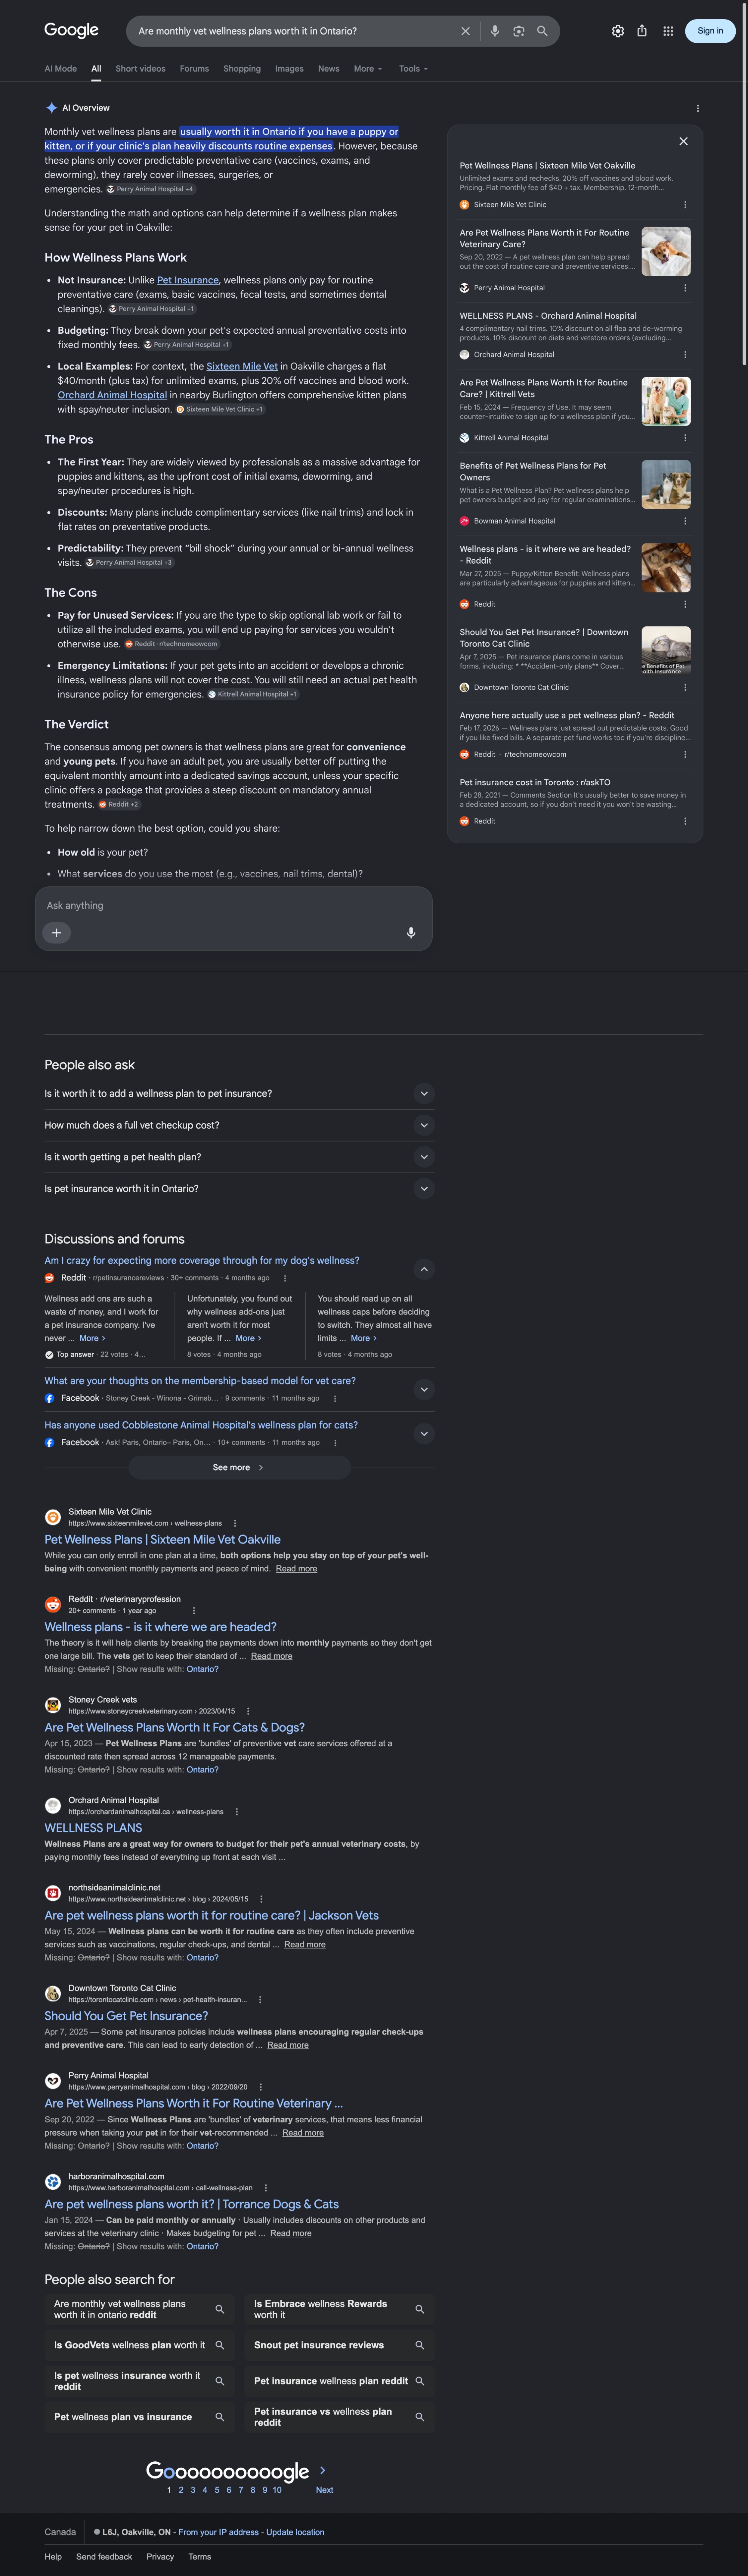
2. **The `/pricing.md` and SMVC Club content.** Google's wellness-plan answer now reads "Sixteen Mile Vet in Oakville charges a flat $40/month for unlimited exams, plus 20% off vaccines and blood work" — quoted from the clinic's own plan page. That query returned generic Banfield and Forbes content on day 0. The machine-readable pricing got read and repeated verbatim.
3. **Claude moved off training data.** On day 0 Claude cited the clinic once. At day 60 it cites the clinic first-party on both the branded reputation query and the tick query, pulling the reviewer-aware detail (in-house ultrasound, full-mouth dental radiography) that the E-E-A-T work put on the page.
## What didn't move
- **"Best vet in Oakville" is still a wall.** Claude and Google both leave the clinic out of their top-list answer for the head local-commercial query; only ChatGPT ranks it (third). The answer both engines now lead with is Southeast Oakville Veterinary Hospital, which trades on accreditation badges (AAHA, Fear Free, Cat Friendly) the clinic does not currently hold.
- **ChatGPT's count held at 3/7**, but the mix improved: it dropped a weak, buried pricing citation and picked up the heartworm post at a real position.
- **Powassan** stayed at zero across all three engines — the one content bet that has not yet paid out.
## Supporting signals
- **AI citations, measured directly** (Bing AI Performance report — citations in Microsoft Copilot and Bing AI summaries): the site was cited **1,544 times between May 12 and July 7**, and the shape of the curve is the point. It ran at **6.4 citations/day in the first two weeks and 41.6/day in the last two** — a 6.5× climb — peaking at 121 in a single day. Citation volume was sparse through mid-May and ramped hard across June as the content got indexed. This is the leading indicator the manual citation runs above confirm from the demand side.

- **Which crawlers arrived** ([Silo CDP](/products/silo), matched 61-day windows; `ubid` was retired mid-run, so counts use anonymous ID): the bot surge charted at the top of this post is a Googlebot re-crawl (5 → 379 hits) plus the first appearances of AI fetchers — ClaudeBot, Bytespider, Meta's external agent, and Google NotebookLM — none of which touched the site in the prior 61 days. Over the full windows, unique human visitors rose **409 → 1,282 (+213%)** and unique bot agents **62 → 865 (~14×)**.
- **Indexed-page count** (Google Search Console): **35 → 60 indexed pages (+71%)** from the day-0 baseline (May 8) to day 60, while "not indexed" fell from 109 to 81. Google both discovered the new topic archives and pagination and indexed more of what it had already crawled — the router-derived sitemap doing its job.

- **Core Web Vitals** (GSC, Chrome UX field data, mobile): **51 of 51 URLs rated "good," zero poor, zero needs-improvement** as of July 7. Field data only crossed Google's CrUX reporting threshold in mid-June — before that the site had too little real-user traffic to be scored at all — so the result reads as "enough traffic to finally be measured, and every measured URL passes." Desktop still shows insufficient field data; PageSpeed Insights lab data covers that gap.
- **Rich-result eligibility** (Google's Rich Results Test): the homepage validates as **LocalBusiness, Organization, and Review Snippet** — all eligible for rich results — and the blog posts validate as **Article and Breadcrumb**. The `FAQPage` markup is present but no longer surfaces as a Google rich result — Google retired FAQ rich results for most sites — so it now earns its keep by handing AI engines a clean question-and-answer structure to lift from rather than by rendering a SERP dropdown.
## Methodology
7 queries × 3 engines × 2 dates = 42 manual UI captures. Queries were grounded in real Google Search Console data — top impressions, blog-slug matches, and `/pricing.md` content — not plausible-sounding guesses. We measured in the consumer UIs rather than the provider APIs on purpose: the API's web-search tool is a different surface (different backend, no consumer system prompt, no personalisation), so its citation rate is not a reliable proxy for what a real user sees. Screenshots and the per-query rationale live in the agency repo.
## Sources
- The implementation this measures — [Making a vet clinic citable by ChatGPT, Perplexity, and Claude](/insights/sixteen-mile-vet-ai-answer-engine-seo)
- Sixteen Mile Veterinary Clinic — [sixteenmilevet.com](https://www.sixteenmilevet.com)
- Bing AI Performance report — [Bing Webmaster Tools](https://www.bing.com/webmasters)
- Google Search Console — [Page indexing and Core Web Vitals reports](https://search.google.com/search-console/about)
---
## Making a vet clinic citable by ChatGPT, Perplexity, and Claude
URL: https://www.theadpharm.com/insights/sixteen-mile-vet-ai-answer-engine-seo
Source markdown: https://www.theadpharm.com/insights/sixteen-mile-vet-ai-answer-engine-seo.md
Published: 2026-05-09
Updated: 2026-07-09
Category: case-studies
Author: adpharm-digital
Reviewed by: ben-honda
Tags: ai-eo, technical-seo, schema-org, llms-txt, robots-txt, astro, vercel, core-web-vitals, e-e-a-t
> TL;DR: We shipped a coordinated AI-EO + technical SEO pass on [sixteenmilevet.com](https://www.sixteenmilevet.com): allow citation-pathway AI bots and block training-only ones, expose `/llms.txt` and `/pricing.md` at the root, harden authorship and reviewer JSON-LD, replace the hand-rolled sitemap with one derived from the router, and lift Core Web Vitals on the homepage. The work shipped 2026-05-09; the measured 60-day results are in a companion post — [first-party citation rate rose 29% to 38%](/insights/sixteen-mile-vet-ai-answer-engine-seo-results).
[Sixteen Mile Veterinary Clinic](https://www.sixteenmilevet.com) is a single-location practice in Oakville. The site runs on Astro 5 (server output), React 19, and Tailwind 4, deployed to Vercel. The brief was simple: make the site eligible for citation by AI answer engines, tighten the technical-SEO surface, and lift Core Web Vitals on the homepage.
Most of the value was in the order. We started with the crawler policy because a site no engine can reach is invisible no matter how clean its schema is. Authorship came second, because Google's vet-content guidance is strict and the answer engines are converging on the same signals; vague attribution costs rich-result eligibility no matter how fast the page loads. With those two layers right, schema and sitemap hygiene fall into place, because every other signal compounds once the entity model is consistent. Performance came last. It is the most familiar lever, and the smallest one when the layer underneath it is broken.
## Crawler policy: opt in to citation, opt out of training
We rewrote `robots.txt` around a single question: does this bot send users back to the source, or does it just train a model?
- Allowed: GPTBot, ChatGPT-User, OAI-SearchBot, ClaudeBot, Claude-Web, anthropic-ai, PerplexityBot, Perplexity-User, Google-Extended, Applebot, Applebot-Extended, Bytespider, Meta-ExternalAgent, Amazonbot.
- Blocked: CCBot. It feeds Common Crawl, a training corpus with no citation pathway, so allowing it costs bandwidth without earning visibility.
- Crawl-delay: SemrushBot, AhrefsBot, DotBot. Useful tools, kept off the critical path.
This is the cheapest change in the pass. Most clinic sites land at one of two extremes: every bot blocked, or every bot allowed.
## `/llms.txt` and `/pricing.md`
Two flat files now sit at the root of the site, both linked from the sitemap.
`/llms.txt` follows the [proposed standard](https://llmstxt.org/) for giving language models a clean, low-noise summary of the site. Ours covers location, hours, team, plan structure, key URLs, and the disclaimer. A model grounding against the file reads that framing instead of whatever it would otherwise piece together from the marketing pages.
`/pricing.md` is the wellness-plan pricing in machine-readable Markdown: SMVC Club at $40/month, the P.A.L. Plan, exam fee, plan rules. Pricing is the single most-asked question across vet AI queries, and serving it as plain text lets answer engines quote it accurately rather than reconstruct it from scraps.
## Authorship and E-E-A-T
Google's vet-content guidance is strict, and the answer engines are converging on the same signals.
We built a per-post author registry. Posts written by credentialed staff (`Dr. ... DVM`) emit `Person` JSON-LD with the clinic as `affiliation`; non-credentialed authors fall back to `Organization`.
Many of the 92 educational posts were drafted by the editorial team and reviewed by a clinician. The schema layer now enforces that every non-draft post carries either an `author` or a `reviews` array. Reviewer-only posts render "Reviewed by Dr. ..." in the byline and emit `reviewedBy` Person entries alongside the clinic as author.
A `/disclaimer` page plus a per-post editorial disclaimer aside, linked from the footer, tells humans and crawlers that the articles are educational and not a substitute for an exam.
## Structured-data hygiene
The schema layer needed several small fixes, each of which carries an outsized effect on how Google and the answer engines reconcile entities across the site.
We canonicalised every JSON-LD URL to `https://www.sixteenmilevet.com` so `BlogPosting`, the sitemap, and `` in the markup. A dead `BreadcrumbsContentPages` component that was imported but never rendered got deleted on the way through.
## One sitemap, derived from the router
The previous setup had `sitemap-index.xml.ts` + `sitemap-0.xml.ts` plus a hardcoded list of blog slugs. We replaced both with a single `sitemap.xml.ts` driven by the router:
```ts
const decisions: Record = { ... }
```
The change has two consequences worth flagging. Adding a route without a sitemap decision is now a TypeScript error, which catches the most common cause of stale sitemaps. And because blog posts come from the content collection, new articles appear automatically, including the new `/blog/` and `/blog/topic/[/]` paths.
> Astro footnote: pagination pages originally used `getStaticPaths`, which never runs under [`output: "server"`](https://docs.astro.build/en/reference/routing-reference/#getstaticpaths). We swapped to request-time `Astro.params.page` parsing with a redirect-to-page-1 fallback for out-of-range values.
## Topic-based blog archive
The blog grew to 92 posts across ticks, heartworm, fleas, dog allergies, safe foods, and clinic updates. We replaced the flat archive with:
- `/blog`, paginated 12 per page, with a topic-chip filter row.
- `/blog/topic/` archives for each topic, also paginated.
- A single `TOPICS` registry (`src/lib/blog/topics.ts`) feeding archive pages, post breadcrumbs, the sitemap, and the footer column. One file to update; everything else stays in sync.
- Featured-post hero on `/blog`; a "Continue Reading" block on each post with `sessionStorage`-backed visited-state highlighting.
The topic archives matter for AI-EO specifically: they give answer engines clean topical hubs to cite when a user asks a category-shaped question like "tick prevention in Ontario" rather than a long-tail one.
## Dynamic Open Graph images
Every page now has its own 1200×630 OG card, generated on the fly via [`@vercel/og`](https://vercel.com/docs/og-image-generation):
- The `/og/.png` endpoint resolves the title and category label from a server-side registry keyed by path. Nothing about the rendered card comes from the query string. The endpoint cannot be coerced into rendering attacker-controlled text on a `sixteenmilevet.com` URL.
- `SEOHead` falls through: explicit `image` prop, then registered dynamic OG, then static `/ogimage.png`.
- Vercel `includeFiles` bundles the brand fonts and white-logo SVG into the serverless function so the renderer is self-contained.
Every share, link preview, and `og:image` lookup ends up with a branded card without anyone hand-designing one per page.
## Core Web Vitals on the homepage
LCP and CLS feed into both classical SEO and the freshness of any AI summary that re-fetches the page.
- We preloaded Lexend Deca and Open Sans Latin `woff2` subsets in the base `Layout` so above-the-fold text never blocks on font fetch.
- We preloaded the homepage hero image with `fetchpriority="high"`. Below-the-fold `
You tend to converge toward generic, "on distribution" outputs. In frontend
design, this creates what users call the "AI slop" aesthetic. Avoid this:
make creative, distinctive frontends that surprise and delight. Focus on:
Typography: Choose fonts that are beautiful, unique, and interesting. Avoid
generic fonts like Arial and Inter; opt instead for distinctive choices that
elevate the frontend's aesthetics.
Color & Theme: Commit to a cohesive aesthetic. Use CSS variables for
consistency. Dominant colors with sharp accents outperform timid,
evenly-distributed palettes. Draw from IDE themes and cultural aesthetics
for inspiration.
Motion: Use animations for effects and micro-interactions. Prioritize
CSS-only solutions for HTML. Use Motion library for React when available.
Focus on high-impact moments: one well-orchestrated page load with staggered
reveals (animation-delay) creates more delight than scattered
micro-interactions.
Backgrounds: Create atmosphere and depth rather than defaulting to solid
colors. Layer CSS gradients, use geometric patterns, or add contextual
effects that match the overall aesthetic.
Avoid generic AI-generated aesthetics:
- Overused font families (Inter, Roboto, Arial, system fonts)
- Clichéd color schemes (particularly purple gradients on white backgrounds)
- Predictable layouts and component patterns
- Cookie-cutter design that lacks context-specific character
Interpret creatively and make unexpected choices that feel genuinely designed
for the context. Vary between light and dark themes, different fonts,
different aesthetics. You still tend to converge on common choices (Space
Grotesk, for example) across generations. Avoid this: it is critical that
you think outside the box!
```
A bug worth knowing about: the skill's instruction *"never converge across generations"* is technically incoherent. Claude has no memory of previous conversations, so the model has no way to know what it did last time. Independent researcher Justin Wetch flagged this in [PR #210](https://github.com/anthropics/skills/pull/210) and rewrote the rule to be actionable in a single generation; the PR reportedly produced a 75% win rate across model tiers in his own testing. If you're using a community fork, you may already be on his version.
## Pick an aesthetic family. Then mix two
The slop is the *average* of all marketing prose on the open web. The fastest way to leave the average is to anchor the prompt to a named aesthetic that isn't in the middle.
The community has organized counter-aesthetics into families. A small subset from [rohitg00/awesome-claude-design](https://github.com/rohitg00/awesome-claude-design):
| Family | Reference brands | Use it for |
|---|---|---|
| Editorial Minimalism | Linear, Stripe, Vercel, Mintlify | Read-heavy SaaS, docs, pricing |
| Terminal-Core | Ollama, Warp, Raycast, OpenCode | Developer tools, CLI products |
| Warm Editorial | Anthropic, Notion, Resend, Substack | Prosumer, knowledge tools |
| Data-Dense Pro | ClickHouse, PostHog, Grafana, Sentry | Analytics, dashboards |
| Cinematic Dark | Runway, ElevenLabs, Midjourney | AI products, creator tools |
| Playful Color | Figma, Duolingo, Mailchimp, Cal.com | Consumer, education |
| Glass / Soft-Futurism | Apple, Arc, Airbnb, Spotify | Premium consumer |
| Neon Brutalist | The Verge, Pitchfork, PlayStation | Statement marketing pages |
| Cult / Indie | A24, Criterion, Letterboxd, Obsidian | Anything that needs to feel like it took courage |
Naming one family is good. Naming a *remix* of two is better. "Linear's typography discipline plus Pitchfork's editorial color" gives Claude two anchors to triangulate between, and the result reads as designed rather than copied. Ruben Hassid's prompt template in [his Substack post](https://ruben.substack.com/p/claude-design) leans on this directly: tone should feel "a mix of [reference] + [reference]."
## The DESIGN.md
This is the convention that makes the difference between "every prompt is a new aesthetic" and "the brand survives the project."
A `DESIGN.md` is a markdown file Claude reads as your design system before generating anything. It came from Google Stitch originally and is now a *de facto* standard across Claude Design, Cursor, Lovable, v0, and Bolt. The canonical structure runs about nine sections: visual theme, color tokens, typography rules, component stylings, layout principles, depth and elevation, do's and don'ts, responsive behavior, and a closing rejection clause that tells the agent what *not* to do.
You don't have to write one from scratch. The [VoltAgent](https://github.com/VoltAgent/awesome-design-md) and rohitg00 catalogs together ship more than sixty ready-made DESIGN.md files for brands like Linear, Stripe, Notion, Airbnb, and Ferrari. Drop one in. Treat it as remix material, not a clone.
The simplest sanity check Hassid recommends: upload a DESIGN.md, then generate the same dashboard or pricing page using three different brand systems. If the three look meaningfully different, the system is being applied. If they look like the same template wearing different colors, something in the DESIGN.md isn't loading.
## Prompt with four inputs locked in
Hassid's framework, echoed across most of the launch-week walkthroughs:
> Goal. Layout. Content. Constraints.
Example:
> *"Build a pricing page for [product]. 3 tiers, annual/monthly toggle, sticky CTA on mobile. Mobile-first responsive. Use our Primary Button component. Match the tone of our existing homepage."*
Vague prompts ("make a landing page") return Anthropic's statistical center. Specific prompts with named components and named constraints return work that uses your design system.
For pitch-deck-style landing pages, the template that's been widely copied since launch:
> *"Create a high-fidelity landing page designed to raise $[FUNDING AMOUNT] from [TARGET INVESTORS] for '[PRODUCT NAME]' — [short product description]. Target audience: [audience]. Tone should feel [emotion] — think a mix of [reference site] + [reference site] + [ecosystem]."*
The "mix of two or three references" pattern is the cookbook's "reference design inspirations" strategy made operational. Anchoring to two or three named brands forces a remix.
## Iterate in Tweaks. Don't re-prompt
The single most-repeated launch-week complaint, including Peter Yang's: *"Fun, but burns through usage fast."* Claude Design runs on a weekly meter that sits separately from chat and Claude Code. Vision-heavy work on Opus 4.7 pulls a lot of tokens, and unstructured re-prompting is the fastest way to spend through the allowance.
The fix is not to use the tool less. It is to stop re-prompting for refinements. Claude Design ships inline comments and adjustment-knob "Tweaks" sliders for spacing, color, and layout. Those are the right tools for "make this padding bigger" or "swap this button variant." Re-prompting is the right tool for "I want to try a different direction entirely."
[John Voorhees at MacStories](https://www.macstories.net/stories/hands-on-with-anthropic-labs-claude-design-preview/) named this the 95% pattern: comment-on-element covered roughly 95% of what he needed once he adapted to it. When a comment occasionally vanishes before Claude reads it (a known bug), copy the comment into the chat panel and it lands every time. Use comments for targeted, component-level tweaks. Use chat for structural changes, new sections, aesthetic shifts.
## Hand off to Claude Code. Don't ship from Claude Design
The handoff bundle is a first-class feature for a reason. Claude Design is for ideation and design systems; production-grade code, accessibility, performance, integration testing, and SEO belong in Claude Code or a real engineering pipeline. The much-quoted "20+ prompts in other tools became 2 in Claude Design" figure should be read as *to a working prototype*, not *to production*. The [Scroll agency post](https://agence-scroll.com/en/blog/claude-design-anthropic-2026-guide) is explicit: a Claude Design prototype is the starting line for production work, not the finish line.
Multiple agencies report that Claude Design output looks shippable but has weak generated design-system variants, taped-together auth, and database designs that don't scale. The output is fast. Fast is the whole pitch. It is not the same as done.
## What still goes wrong
Things that won't show up in the launch posts and are worth knowing.
The design system anchors at scaffold time. If you want to try a different brand, start a fresh project. Mid-project brand swaps muddle the tokens.
Long sessions on Opus 4.7 degrade. Reports of $120 of API credits spent in a single session with disappointing output trace to mega-threads. Break the work into smaller, focused conversations rather than one running session.
Multi-file Figma libraries are hit-or-miss. Single pages import cleanly. Complex `.fig` libraries with components and variants often fail. Re-export simplified.
There is no Figma export at launch. You can export to Canva, PDF, PPTX, HTML, and shareable URLs. If your team's source of truth is Figma, you will round-trip via Canva or HTML.
Cross-conversation skill instructions are placebo. "Don't converge across generations" cannot work, because Claude has no memory between sessions. Use per-generation theme-locks and named aesthetic families instead.
## What it produces depends entirely on how you brief it
Anthropic's launch post quotes Aneesh Kethini at Datadog cleanly: *"What used to take a week of back-and-forth between briefs, mockups, and review rounds now happens in a single conversation."* That is true. It is also conditional.
Without scaffolding (a DESIGN.md, the cookbook system prompt, a named family, a multi-reference brief), Claude Design produces the same statistical-center output as every other AI design tool, just faster. With the scaffolding, you get something that doesn't look AI-generated.
Malewicz's most cutting line in the teardown is worth holding on to. The tool produces *output*, not *judgment*. Choosing which of ten generated dashboards to ship is still your job. So is deciding when the prototype is done enough to leave Claude Design and move to Claude Code, where the production work actually happens.
The shortest version of the formula: pick two aesthetic families to remix, borrow or write a DESIGN.md, drop the cookbook's anti-slop fragment into the project, prompt with goal-layout-content-constraints, iterate in Tweaks and comments, and hand off to Claude Code for production.
## Sources
- Anthropic — [Introducing Claude Design](https://www.anthropic.com/news/claude-design-anthropic-labs) (April 17, 2026)
- Prithvi Rajasekaran, Anthropic — [Prompting for frontend aesthetics (Claude Cookbook)](https://platform.claude.com/cookbook/coding-prompting-for-frontend-aesthetics) (October 21, 2025)
- Anthropic — [frontend-design SKILL.md](https://github.com/anthropics/skills/blob/main/skills/frontend-design/SKILL.md)
- Justin Wetch — [PR #210: Improve frontend-design skill clarity and actionability](https://github.com/anthropics/skills/pull/210)
- rohitg00 — [awesome-claude-design](https://github.com/rohitg00/awesome-claude-design)
- VoltAgent — [awesome-design-md](https://github.com/VoltAgent/awesome-design-md)
- Michał Malewicz — [Will Claude Design replace designers?](https://michalmalewicz.medium.com/will-claude-design-replace-designers-f92623f3befe) (Medium, April 2026)
- Ruben Hassid — [Claude Design](https://ruben.substack.com/p/claude-design) (How to AI, Substack)
- John Voorhees — [Hands-On with Anthropic Labs' Claude Design Preview](https://www.macstories.net/stories/hands-on-with-anthropic-labs-claude-design-preview/) (MacStories)
- Scroll Agency — [Claude Design (Anthropic): The Complete 2026 Guide](https://agence-scroll.com/en/blog/claude-design-anthropic-2026-guide)
---
## A working playbook for Claude Code Skills on Opus 4.7
URL: https://www.theadpharm.com/insights/claude-code-skills-opus-4-7-playbook
Source markdown: https://www.theadpharm.com/insights/claude-code-skills-opus-4-7-playbook.md
Published: 2026-04-24
Category: ai-and-tech
Author: adpharm-digital
Reviewed by: ben-honda
Tags: claude-code, skills, opus-4-7, prompting, agents, claude
> TL;DR: Skills are markdown files Claude reads when relevant. The description field decides whether a skill ever triggers. Opus 4.7 takes instructions literally, runs through a heavier tokenizer, and won't let you reach for `temperature` anymore. The fix most teams are missing: a per-skill description cap that silently disables skills past a certain count.
You wrote a Skill. Claude ignored it.
Not bad output. No output. The skill sat on disk, the description was on the right topic, and Claude defaulted to its own behaviour anyway. Nine times out of ten it isn't bad prose. It's a structural issue you can't see.
This is the working playbook for [Claude Code](https://code.claude.com/docs/en/skills) Skills on Opus 4.7. It synthesises Anthropic's [engineering post](https://www.anthropic.com/engineering/equipping-agents-for-the-real-world-with-agent-skills), the official [API docs](https://platform.claude.com/docs/en/agents-and-tools/agent-skills/overview), and the [Claude Code Skills docs](https://code.claude.com/docs/en/skills), with a focus on the parts that are easy to get wrong.
## What a Skill is, briefly
A Skill is a folder. Inside the folder is a file called `SKILL.md`. At the top of `SKILL.md` is YAML frontmatter, and the rest is markdown. That's it.
Anthropic [shipped Skills as an open standard on December 18, 2025](https://www.anthropic.com/engineering/equipping-agents-for-the-real-world-with-agent-skills). OpenAI, Google, GitHub Copilot, and Cursor adopted the same format within weeks. [Simon Willison](https://simonwillison.net/2025/Oct/16/claude-skills/) called it "maybe a bigger deal than MCP." It probably is.
The reason it scales is progressive disclosure. Three tiers:
| Tier | What loads | When |
|---|---|---|
| 1 | The skill's name and description | Every session, for every installed skill |
| 2 | The body of `SKILL.md` | When Claude decides the skill is relevant |
| 3 | Bundled files (scripts, references, templates) | Only when explicitly read or run |
The metadata at tier 1 is cheap. About eighty tokens per skill. You can install forty skills and pay roughly fifteen hundred tokens of startup overhead. The body at tier 2 only loads when triggered. The bundled files at tier 3 only load when Claude reaches for them; a 500-line script that returns a 50-token result is essentially free at the model's level.
Phil Whittaker [reframed this](https://dev.to/phil-whittaker/progressive-discovery-a-better-mental-model-for-agent-skills-51bd) as "progressive discovery." The skill is a passive resource on disk. Claude is the active reasoner pulling content as needed. Useful framing. Structure your skill so Claude can find what it needs at each layer and decide whether to go deeper.
## The description is the whole game
The description is the only field Claude sees at startup. It decides whether the skill ever loads. If the description is wrong, nothing else in the skill matters.
The rules are tight. Third person. Up to 1,024 characters. Both *what* the skill does and *when* to use it. Opens with a verb. The name is a separate field; up to 64 characters, lowercase letters and hyphens, gerund-ish (`processing-pdfs`).
And, as Anthropic's own [skill-creator](https://github.com/anthropics/skills) puts it, the description should be *slightly pushy*. Claude undertriggers skills more often than it overtriggers. A polite description loses.
Here's the contrast Anthropic ships in its own docs.
Won't trigger reliably:
```yaml
description: This skill helps with PDFs and documents.
```
Triggers cleanly:
```yaml
description: >
Comprehensive PDF manipulation toolkit for extracting text and tables,
creating new PDFs, merging/splitting documents, and handling forms.
Use when Claude needs to fill in a PDF form or programmatically process,
generate, or analyze PDF documents at scale. Use for document workflows
and batch operations. Not for simple PDF viewing or basic conversions.
```
Four useful signals: specific verbs, concrete use cases, trigger contexts, explicit boundaries. The "not for X" line is what keeps the skill from triggering on the wrong tasks.
One rule that's easy to miss. Keep the workflow *out* of the description. Jesse Vincent, author of [obra/superpowers](https://github.com/obra/superpowers), the most-installed skill plugin in the wild, flags it directly in his own writing skill. If you summarise the workflow in the description, Claude follows the description and never reads the skill. The description carries triggers. The body carries workflow. They are different jobs.
## The silent-truncation trap
This is the most common cause of "my skill exists but nothing happens."
Claude Code combines every installed skill's name and description into a budget that sits in the system prompt. The budget [scales as 1% of the context window](https://code.claude.com/docs/en/skills), with an 8,000-character fallback. Past the budget, descriptions get silently shortened. All names stay. Descriptions get truncated to fit. The keywords Claude needs to match your request quietly disappear.
There is also a per-entry cap of 1,536 characters and, in the `/skills` listing itself, a 250-character cap on each description.
Two practical implications.
Front-load the description. The most important trigger phrases (verbs and user-language keywords) go in the first sentence. If the truncator gets you, it cuts the back half, not the front.
Raise the budget when you have many skills. The default is fine for ten or twenty. Past about fifty, you start losing them silently. Override:
```bash
SLASH_COMMAND_TOOL_CHAR_BUDGET=30000 claude
```
If a skill that "should" be triggering isn't, this is the first thing to check.
## The 5,000-token preservation window
Once a skill triggers, its body enters the conversation as a single message and stays there. When the context fills and Claude Code auto-compacts, the [first 5,000 tokens of each invoked skill](https://code.claude.com/docs/en/skills) are preserved. The combined budget across re-attached skills is 25,000 tokens, filling from most-recently-invoked. Older skills can drop entirely after compaction.
Translation for the writer of the skill: the first 5,000 tokens of `SKILL.md` are the standing instructions. Anything past that is for-this-task-only and may not survive compaction in long sessions.
That maps onto a body length most teams overshoot. Anthropic's own [internal guide](https://resources.anthropic.com/hubfs/The-Complete-Guide-to-Building-Skill-for-Claude.pdf) says under 5,000 words. The practical sweet spot is closer to 2,000–3,000 tokens. Past that, Claude's attention to the bottom of the file dilutes whether the model "has access" or not.
A useful test. Would removing the bottom third of your `SKILL.md` make the skill measurably worse? If not, the bottom third was filler.
## Scripts beat prose for anything deterministic
The under-used part of Skills is the scripts directory. Anything deterministic (validation, parsing, conversion, lint, schema checks) belongs in a script the skill calls, not in prose the skill recites.
The reason is the context window. When Claude runs `validate_form.py`, the script's code never enters the conversation. Only its stdout does. A 500-line Python validator that returns "Validation passed" or three specific error messages is essentially free at the model's level.
This is also where Simon Willison's framing earns itself. Skills as "the spirit of LLMs": markdown plus pre-written scripts the model composes when it needs them. You're not encoding a rule in 200 lines of cautious prose Claude has to read every time. You're encoding it in a deterministic check the model runs, and using prose only for the parts an LLM is good at.
Bundling decisions in practice:
| Content | Where it goes | Why |
|---|---|---|
| Always-relevant procedure | `SKILL.md` body | Used every invocation |
| Sometimes-relevant detail | `references/foo.md`, linked from body | Only loads when needed |
| Deterministic computation | `scripts/*.py` | Code never enters the context window |
| Large reference (schemas, API docs) | `references/*.md` | No cost until read |
| Templates, boilerplate | `templates/` | Claude reads and adapts |
One detail that catches a lot of people. When you reference a bundled file, write it as a command, not a hint. *"If the user requests form filling, read references/FORMS.md before proceeding"* gets followed. *"For form-filling, see FORMS.md"* often doesn't. The Anthropic docs flag missed connections — references Claude doesn't follow — as one of the most common iteration findings.
## What 4.7 changed for skills
[Opus 4.7 shipped on April 16, 2026](https://platform.claude.com/docs/en/about-claude/models/whats-new-claude-4-7). It's materially different from 4.6 in ways that change how skills behave.
It takes instructions literally. A hint that worked on 4.6, something like *"produce a summary, you know, the usual,"* won't be filled in on 4.7. The model executes what's there, not what was implied. If your skill on 4.6 worked partly because Claude generalised your intent, 4.7 will expose that. Spell out audience, format, length, voice. Boris Cherny, who leads Claude Code at Anthropic, said on launch day he needed "a few days to learn how to work with it effectively." That's the adjustment.
Default Claude Code effort is now `xhigh`, a new tier between `high` and `max`. For coding and agentic work, design your skill assuming the model is running at `xhigh`.
The tokenizer changed. English content runs roughly one to one-and-a-third times as many tokens as on 4.6, per Anthropic's number. Non-Latin scripts are more efficient. The same `SKILL.md` is more expensive than it was. Context discipline matters more, not less.
Sampling parameters return errors. No more `temperature`, `top_p`, `top_k`. Skills that depended on tuning sampling now break with a 400.
Adaptive thinking is the only thinking-on mode. Thinking content is hidden in the response stream by default. If your skill's UX showed reasoning, opt in with `display: "summarized"` explicitly.
Mid-output self-correction is real. The model now flags and fixes its own inconsistencies inline. Instructions like *"double-check your ordering before finalising"* or *"cross-check totals before returning"* actually get compliance, where they were aspirational on 4.6. Analysis skills can lean on this.
High-resolution vision: 2576 px / 3.75 MP, up from 1568 px / 1.15 MP, with 1:1 pixel-coordinate mapping. Skills that ask Claude to verify a layout against a screenshot, count UI elements, or click coordinates are substantially more reliable. High-res images cost more tokens; downsample when the fidelity isn't load-bearing.
Task budgets, in beta, give Claude a rough token budget across an agentic loop. Useful for skills that orchestrate long work: deploys, multi-file refactors, doc pipelines. Anthropic reports a meaningful drop in task abandonment on long horizons.
Don't reach for the 1M context just because you can. Quality starts degrading well before that, around the 400,000-token mark. Progressive disclosure is more important on 4.7, not less.
## Test the way you mean to ship
The most useful testing practice in the working community is the TDD-for-skills loop, popularised by [obra/superpowers](https://github.com/obra/superpowers). Write a pressure scenario. Run it against a subagent *without* the skill, and watch it fail. That's the baseline. Then write the skill. Run again. Watch it pass. Refactor to close loopholes.
The principle is uncomfortable and correct. If you didn't watch an agent fail without the skill, you don't know whether the skill teaches the right thing.
Test triggering and execution separately. A skill can fail because Claude never picks it up (description problem), or because Claude picks it up and produces the wrong output (body problem). Different fixes. Don't conflate them.
Cover three classes of prompts: normal usage, edge cases, and out-of-scope. The skill should fire on the first two and stay quiet on the third. Simple one-step queries like "read this PDF" sometimes don't trigger any skill at all, regardless of description. Complex multi-step queries are a better test.
## The build-it-or-not test
The most useful rule in Anthropic's playbook is also the most boring. Build a skill only if you've done the task five times already and expect to do it ten more times.
The shape of the failure when you skip this: a half-finished skill nobody trusts, a description that doesn't trigger because the use case was hypothetical, prose that hedges every claim because the author wasn't sure what the right move was. Speculative skills are wasted work.
The corollary. A running list of tasks you've done by hand more than five times is the best skill backlog you can have. Watch your own friction. The skill you should write next is the one whose work you've already done in this conversation.
## A short pre-ship checklist
Anthropic's full checklist runs about fifty bullets. The five that matter most:
1. The description is third person, opens with a verb, names *both* what the skill does and when to use it, and includes one explicit non-trigger.
2. The body is around 500 lines or under. The first 5,000 tokens contain the standing instructions, on the assumption that auto-compaction may drop the rest in long sessions.
3. Anything deterministic is in a script in `scripts/`, not prose in the body.
4. References to bundled files are written as commands ("read X before proceeding"), not as hints ("see X").
5. You've actually run the skill against three realistic prompts and confirmed it doesn't trigger on a deliberately out-of-scope one.
The full guide that the Anthropic team [published as a PDF](https://resources.anthropic.com/hubfs/The-Complete-Guide-to-Building-Skill-for-Claude.pdf) is worth reading once. After that, the only thing that improves your skill writing is failure data: skills that didn't trigger, skills Claude ignored, skills that triggered on the wrong things. Keep the misses. They're the brief for the next iteration.
The frustrating part is that none of this is hidden. The truncation, the compaction window, the description rules: all of it sits in the docs. The reason skill writing has a learning curve in 2026 is that "write the markdown" is the easy part, and "write the markdown so Claude actually reads it under the constraints of a finite system prompt" is the part that takes practice.
## Sources
- Anthropic Engineering — [Equipping agents for the real world with Agent Skills](https://www.anthropic.com/engineering/equipping-agents-for-the-real-world-with-agent-skills) (December 18, 2025)
- Anthropic — [Agent Skills overview](https://platform.claude.com/docs/en/agents-and-tools/agent-skills/overview) (Claude API docs)
- Anthropic — [Extend Claude with skills](https://code.claude.com/docs/en/skills) (Claude Code docs)
- Anthropic — [What's new in Claude Opus 4.7](https://platform.claude.com/docs/en/about-claude/models/whats-new-claude-4-7)
- Anthropic — [The Complete Guide to Building Skills for Claude (PDF)](https://resources.anthropic.com/hubfs/The-Complete-Guide-to-Building-Skill-for-Claude.pdf)
- Simon Willison — [Claude Skills are awesome, maybe a bigger deal than MCP](https://simonwillison.net/2025/Oct/16/claude-skills/) (October 16, 2025)
- Jesse Vincent — [Superpowers: How I'm using coding agents](https://blog.fsck.com/2025/10/09/superpowers/) and [obra/superpowers on GitHub](https://github.com/obra/superpowers)
- Phil Whittaker — [Progressive Discovery: A Better Mental Model for Agent Skills](https://dev.to/phil-whittaker/progressive-discovery-a-better-mental-model-for-agent-skills-51bd)
- [anthropics/skills](https://github.com/anthropics/skills) — Anthropic's official skill collection
---
## Two Google image models, two jobs: a working prompt guide for Nano Banana Pro and Nano Banana 2
URL: https://www.theadpharm.com/insights/nano-banana-pro-and-2-prompt-guide
Source markdown: https://www.theadpharm.com/insights/nano-banana-pro-and-2-prompt-guide.md
Published: 2026-04-17
Category: ai-and-tech
Author: adpharm-digital
Reviewed by: ben-honda
Tags: nano-banana, gemini-3, image-generation, ai-design-tools, photoreal-prompting, prompting
> TL;DR: Google now ships two image models on Gemini 3. Nano Banana Pro for hero shots, Nano Banana 2 for everything else. Both are reasoning models with the LLM in front of the image generator, which means most of the prompt habits from the original Nano Banana, or from your Stable Diffusion days, actively hurt now. Use real prose, not tag soup. Name the camera. Stay in-thread to edit. Ask for "visible pores, not airbrushed." Generate at 2K, ship at served size.
## Two models, two jobs
Google released [Nano Banana Pro](https://deepmind.google/models/gemini-image/pro/) (`gemini-3-pro-image-preview`) in November 2025, and Nano Banana 2 (`gemini-3.1-flash-image-preview`) in February 2026. Despite the name, they're a long way from the original Nano Banana that shipped on Gemini 2.5 Flash Image. They're not diffusion models. They're transformer-based image generators with a Gemini 3 reasoning model sitting in front, planning the scene before anything renders.
Pro is the slower, more expensive one. It can call live Google Search, mix up to fourteen reference images, render legible text in multiple languages, and generally handles anything you'd put on a hero or in a brand-critical surface. Nano Banana 2 is roughly twice as fast, cheaper, and runs the same architecture tuned for throughput.
Practical rule: Pro for the few hero images per page; NB2 for everything else.
| Capability | Nano Banana Pro | Nano Banana 2 | Original Nano Banana |
|---|---|---|---|
| Resolutions | 1K / 2K / 4K | 0.5K / 1K / 2K / 4K | ~1K |
| Aspect ratios | 1:1, 3:2, 2:3, 3:4, 4:3, 4:5, 5:4, 9:16, 16:9, 21:9 | + 1:4, 4:1, 1:8, 8:1 banners | Limited |
| Reference images | Up to 14 | Up to 14 | ~3 |
| Text rendering | State of the art, multilingual | ~87–96% on benchmarks | Weak |
| Search grounding | Yes | Yes | No |
| Cost per image | ~$0.039 to $0.151 by resolution | Cheaper | Cheapest |
4K costs roughly 2.3× a 1K image and is overkill for most LCP-sensitive web pages. Generate at 2K, then re-encode to AVIF or WebP at the actual served size.
## What changes when the model can think
The thing that breaks every old habit is this: there's an LLM between your prompt and the image. It plans before it renders, it can call tools, and it parses prose. A useful framing: Flux is an image generator that happens to include a VLM; Nano Banana Pro is a reasoning system that happens to output images.
Three consequences fall out of that.
The first is that natural language beats tag soup. Google's own [Ultimate prompting guide for Nano Banana](https://cloud.google.com/blog/products/ai-machine-learning/ultimate-prompting-guide-for-nano-banana) is explicit about it: drop the *4k, masterpiece, ultrarealistic, trending on artstation* spam. The reasoning front-end parses prose. Tag lists from the Stable Diffusion 1.5 era look to it like low-information noise, and they actively pull the output toward the centre. Descriptive sentences carry more signal.
The second is that specificity gets compressed into latent priors. "Hasselblad X2D, 135mm, f/2.8" triggers the model's medium-format and portrait priors: higher dynamic range, tighter compression, denser texture in the skin. "Professional camera" doesn't trigger anything. The same goes for film stocks. *Kodak Portra 400, Fujifilm Pro 400H, Cinestill 800T, Arri Alexa colour science*: each name pulls the output toward a real-world look the model has seen.
The third is that "visible pores, not airbrushed" is the single most-cited anti-plastic phrase. Multiple community prompt libraries converge on that exact wording. The negation suppresses a strong "beautify" prior baked into training data. Nothing else seems to do the same thing as reliably.
## A template you can copy
A starting shape that works for portraits, products, and lifestyle shots:
```
A [shot type] of [specific subject with materials/age/wardrobe], [doing what],
in [setting with time of day]. Lit by [specific lighting setup].
Shot on [camera body] with a [focal length] lens at [aperture], [DOF descriptor].
[Colour/film stock/grade]. Visible [texture cues].
Aspect ratio [X:Y]. Photorealistic. No text, no watermark.
```
Filled in for a SaaS landing page hero:
> A medium three-quarter shot of a 34-year-old product designer in a charcoal merino sweater, leaning over a sketch on a walnut desk, in a sunlit Brooklyn studio at 9am. Lit by soft window light from camera-left with a subtle bounce on the right. Shot on a Sony A7IV with an 85mm f/1.4 at f/2.0, shallow depth of field with the background falling into a clean bokeh. Kodak Portra 400 colour science, natural skin tones. Visible skin pores, baby hairs at the temple, fine fabric weave on the sweater. Aspect ratio 16:9. Photorealistic editorial photography. No text, no watermark.
The product version of the same shape is shorter. No human means no pore-cluster or asymmetry instructions, but you keep the named camera, the lens, the aperture (`f/8` to `f/11` for product), and one specific surface noun (concrete, linen, seamless paper) instead of "minimal background."
## Edit in-thread, not by re-rolling
This is the change most likely to surprise you if you came from the original Nano Banana. The Gemini 3 image preview API attaches encrypted "thought signatures" to each turn, and on `gemini-3-pro-image-preview` and `gemini-3.1-flash-image-preview` those signatures are *strictly required* on subsequent edits. Missing them returns a 400 error. The practical effect is that staying in the same conversation thread means the model literally remembers the composition logic. Starting a fresh conversation throws all of that away.
The phrasing the [Google Cloud guide](https://cloud.google.com/blog/products/ai-machine-learning/ultimate-prompting-guide-for-nano-banana) recommends, and that the [Gemini 3 Pro Image docs](https://ai.google.dev/gemini-api/docs/models/gemini-3-pro-image-preview) echo, is to ask for one change at a time and explicitly anchor everything else:
```
Using this image, [single change]. Keep everything else exactly the same:
preserve composition, lighting direction, colour grade, and subject features.
```
If you treat each prompt as a re-roll instead, you'll watch the subject drift between turns. The fix is one sentence in the prompt and a habit of staying in-thread.
## The anti-AI-look stack
Things to weave into any realistic prompt, on top of the camera and film stock:
- *Natural skin texture with visible pores, not airbrushed, not waxy.*
- *Subtle skin imperfections: faint freckles, slight asymmetry, fine flyaway hairs.*
- *Natural catchlights in both eyes.*
- *Imperfect, lived-in environment.* (Kills the sterile-stock-photo vibe.)
- *Subject slightly off-centre, leading look-room left.*
Negatives don't use the Stable Diffusion `(plastic skin:1.4)` syntax. Nano Banana parses them as natural-language instructions. Append at the end:
> Avoid: plastic skin, waxy appearance, airbrushed look, doll-like eyes, fused fingers, deformed hands, distorted background text, oversaturation, HDR halos, motion blur on a still subject. No text, no watermark, no logos.
These reduce the failure rate. They don't guarantee anything. The model treats them as instructions, not strict tokens, so run a few generations and prune negatives that fire too often into hallucinated artifacts of their own.
## Multiple references, named characters
Two practices, one principle. Both rely on the model anchoring on named entities and repeated descriptors, not on a hidden seed.
The multi-image formula from the Google docs:
```
[Reference images attached] + [Relationship instruction] + [New scenario]
```
For example: *Using Reference 1 (the model) and Reference 2 (the silk gown), generate a high-end editorial shot of the model wearing the gown on a Milan rooftop at golden hour.* The relationship instruction is the part most people skip; without it, the model doesn't know which reference is doing what.
For character consistency across a series, generate a brand or character sheet first (*"…showing front, three-quarter, and side views on a neutral background"*), then in every subsequent prompt name the character and re-state three to five anchor traits:
> *Mia, short auburn hair, freckles, denim jacket. [New scene.]*
Reference-image anchoring is more reliable than text-only naming. Past five named characters in a single scene, anchoring degrades. Ambience AI's hands-on testing puts the practical ceiling at roughly five named characters and fourteen named objects per series, though that's anecdotal and worth re-testing on your own briefs.
Search grounding is the other lever Pro adds. It can call Google Image Search before generating, useful when you need a real bird species, a specific city skyline, or current product packaging. Trigger phrase: *Use image search to find accurate references of [X], then create…* The caveat is that community testing keeps catching it producing good-looking but factually wrong infographics, so verify any image that carries data.
## Web-specific tactics
The bits that matter once the image is leaving your laptop.
For aspect ratios, use 16:9 for hero and OG images, 4:5 for product detail pages, 1:1 for cards, and 9:16 for mobile and social. The banner ratios (1:8, 8:1, 1:4, 4:1) are NB2-only. Specify the ratio in the prompt *and* in the API parameter where one exists; both surfaces respect it.
Generate at 2K by default. 4K is overkill outside print or specific hero contexts and ships at 4 to 8 MB raw, so never serve those directly. Re-encode to AVIF or WebP at the actual served size.
For hero shots that need to work on both light and dark themes, prompt for soft, mid-key lighting against a neutral mid-grey background. The model has no native "transparent on dark or light" mode for photos, but the mid-key range reads cleanly under either theme.
Put any text you want in the image inside `"quotation marks"`, or the model paraphrases. Pro renders quoted strings reliably now, including multilingual; this is the biggest single improvement over v1.
For brand work, lock a logo, two key colours, a palette swatch image, a face or character sheet, and a style reference. Feed that bundle as references on every brand image. Multi-image conditioning is the single most reliable consistency lever.
## Failure modes worth knowing
Some of these will surprise you. Small faces in crowds and wide shots still smear; the model produces "crowd soup" past a certain distance, so don't put critical subjects in the deep background of a wide shot. Hands have improved but not been solved. Holding small objects, intertwined fingers, and complex grips still fail occasionally; negate them explicitly with *no fused fingers, no deformed hands*.
IP and celebrity refusals are silent. A prompt naming a copyrighted character or a public figure returns `finishReason: OTHER` with null content, which looks like a transport failure. Reword to remove the named IP.
Preview API reliability is real. Multiple aggregator blogs report 30 to 45 per cent peak-hour failure rates on the Pro preview during launch quarters, and Google itself acknowledges the preview-status caveat. If you're shipping a production flow that depends on real-time generation, build a fallback chain: Pro to NB2 to a cached prior generation. Catch the failure, don't surface it to the user.
Major edits break realism. Day to night, full background swap, blending three images: all produce uncanny lighting mismatches if you don't tell the model to match the new environment. Add: *match the new lighting direction and colour temperature to the new environment, including cast shadows and rim light.*
Default safety thresholds are now `OFF` on Gemini 2.5 and 3 unless you set them explicitly (Google's safety docs were updated to reflect this in January 2026). Old tutorials telling you to manually relax filters are out of date. If you're getting a refusal, check `finishReason` first; the prompt is rarely the problem.
Every output gets a SynthID watermark. Plan accordingly for any "looks like stock" use case.
## Framings the model treats as permission to render imperfectly
These aren't policy bypasses. They're contextual setups the model interprets as license to render the kind of imperfection that reads as real, and they produce more convincing results than asking for "photorealistic" or "high quality":
- *Documentary photography. Behind-the-scenes still. Candid photojournalism.* Suppresses the model's tendency toward composed, stage-lit perfection.
- *iPhone snapshot, slight motion blur, mixed indoor lighting.* Convincing "real person took this" energy. Useful for UGC-style web imagery.
- *Editorial portrait for The New Yorker / Wired / Monocle.* Triggers higher-fidelity skin and lighting priors than "professional photo."
- *Shot on a disposable camera with direct flash.* Forces grain, harsh shadow falloff, and colour casts that read as authentic.
- *Photograph from [year], with era-specific clothing and tech.* Era-grounded realism beats generic "vintage" every time.
## Where each model sits in the wider field
For most of early 2026, Nano Banana 2 sat at the top of the [LM Arena image leaderboard](https://arena.ai/leaderboard) with an Elo around 1,360. As of May 2026 OpenAI's GPT Image 2 has since taken the top spot by a record margin (1,512 Elo, a +242 lead), but the qualitative picture for working web imagery hasn't changed much. NB2 still leads on multilingual text rendering and search-grounded composition. FLUX.2 Pro is the strongest open and self-hostable option. Midjourney v7 is still the aesthetic leader for editorial mood work, but its text rendering is weak (~71 per cent accuracy) and there's no first-class API.
The hybrid stack a lot of teams use: Midjourney for concept exploration, Nano Banana Pro for the chosen hero with brand text, NB2 for variants and bulk, Photoshop or Firefly for the final pixel polish.
## A closing note
Models update silently. If a technique here stops working, particularly content-policy edges, search-grounding behaviour, or aspect-ratio support, assume the model changed, not your prompt. Re-baseline quarterly.
## References
- Google AI for Developers, [*Gemini 3 Pro Image Preview*](https://ai.google.dev/gemini-api/docs/models/gemini-3-pro-image-preview)
- Google DeepMind, [*Gemini 3 Pro Image — Nano Banana Pro*](https://deepmind.google/models/gemini-image/pro/)
- Google Cloud Blog, [*Ultimate prompting guide for Nano Banana*](https://cloud.google.com/blog/products/ai-machine-learning/ultimate-prompting-guide-for-nano-banana)
- The Keyword (Google blog), [*Nano Banana Pro: Gemini 3 Pro Image model from Google DeepMind*](https://blog.google/innovation-and-ai/products/nano-banana-pro/) and [*Nano Banana 2*](https://blog.google/innovation-and-ai/technology/ai/nano-banana-2/)
- [LM Arena image leaderboard](https://arena.ai/leaderboard)
---
## Brand-fidelity mockups in Claude Code and Google Stitch: what actually steers them off the AI default
URL: https://www.theadpharm.com/insights/claude-code-stitch-brand-mockups
Source markdown: https://www.theadpharm.com/insights/claude-code-stitch-brand-mockups.md
Published: 2026-04-10
Category: ai-and-tech
Author: adpharm-digital
Reviewed by: ben-honda
Tags: claude-code, google-stitch, design-systems, design-md, ai-design-tools, brand-design
> TL;DR: Both tools converge on the same generic AI aesthetic without explicit prohibition. Claude Code rewards heavy upfront constraints — a `CLAUDE.md` plus the right skills. Stitch rewards light prompts plus iterative in-canvas edits. The single most consequential 2026 primitive across both is `DESIGN.md`: write it once from your brand, and both tools read it before generating. Prefer concrete nouns over mood adjectives, real copy over lorem ipsum, and one change per iteration over kitchen-sink prompts.
## What the AI default actually looks like
Both Claude Code and Google Stitch sample from the statistical centre of design decisions on the open web. Anthropic has a name for it: *distributional convergence*, the term they use in the [November 2025 frontend-design post](https://claude.com/blog/improving-frontend-design-through-skills) to describe what happens when you give the model no aesthetic constraints. The default look: Inter as the body font, a white hero with a purple gradient, three-up feature cards with icon and headline and one-line description, hamburger nav on mobile, and a carousel of testimonials nobody asked for. Stitch lands in the same neighborhood by a different route. Its Gemini renderer defaults to Material Design 3, light mode, and generic SaaS, but the destination is the same.
The whole job, for both tools, is steering away from that centre. Almost everything below is a tactic for doing that.
## Real copy beats lorem ipsum, for mechanical reasons
The first lever is the one most people skip. Real copy length tells the layout how to behave. A hero h1 that has to carry six words lays out differently from one that carries sixteen. A pricing card grid that fits eight short bullets fits four long ones differently. Lorem ipsum gives the layout a rhythm that doesn't match production, and the layout problems hide until production copy arrives.
Anthropic's official `frontend-design` skill doesn't require copy as input, but it pushes the agent to commit to a specific *purpose* before touching code: who uses this, what problem does it solve. Practitioners almost universally extend that by handing Claude the actual brand copy. A widely-cited rule from Engr Mejba Ahmed's `CLAUDE.md` template, *never use Lorem Ipsum; generate realistic copy*, has become a community default. Without it, placeholder text scatters through components like confetti.
For Stitch the calculus is slightly different. Direct Edits, added in the March 2026 update, let you click any text element and replace it without regenerating the screen. That makes it reasonable to seed Stitch with rough copy and refine the words inline afterward, the inverse of the Claude Code flow where copy is part of the generation prompt. Either way, the headline and primary CTA earn their specificity early. Vague prompts like "modern, clean fitness app" produce the centre. A specific noun like *Japandi-styled tea store* (the example Vincent Nallatamby uses in the official Stitch Prompt Guide) gets you a specific design treatment.
A useful rule of thumb: provide the copy that drives layout (hero, value prop, features, primary CTA) and let the tool fill in the rest, then edit. Trying to dictate every footer link and microcopy label is what produces 5,000-character prompts that overflow the context window. Stitch's own product team recommends starting with plain language and complexifying screen by screen.
## Constraints at the right altitude
Anthropic's frontend-design post is explicit about this. Don't hardcode every hex; don't give vague high-altitude direction. The middle altitude is targeted language about specific design dimensions, with concrete examples and prohibitions. The cookbook's `TYPOGRAPHY_PROMPT` is the exemplar: a prohibited list, then categorised alternatives, then a principle, then a quantitative rule.
> **Never use:** Inter, Roboto, Open Sans, Lato, default system fonts.
> **Impact choices:**
> - Code aesthetic: JetBrains Mono, Fira Code, Space Grotesk
> - Editorial: Playfair Display, Crimson Pro, Fraunces
> - Startup: Clash Display, Satoshi, Cabinet Grotesk
> - Technical: IBM Plex family, Source Sans 3
>
> **Pairing principle:** High contrast = interesting. Display + monospace, serif + geometric sans, variable font across weights.
>
> **Use extremes:** 100/200 weight vs 800/900, not 400 vs 600. Size jumps of 3x+, not 1.5x.
This shape (prohibitions, categorised alternatives, a principle, numbers) is what every high-rated community skill copies. It works because it gives the model something specific to do *and* something specific not to do. "A nice sans-serif" is what doesn't work; "anything except Inter, Roboto, Space Grotesk; pick from the editorial or technical shelves" is what does. Anthropic's own warning is that even with prohibitions in place, the model will converge on Space Grotesk as a "safe distinctive font," so add it to the prohibited list once you've seen it appear too often.
The same altitude applies to color, motion, density, and backgrounds. Pick a dominant color and a sharp accent rather than asking for "a cohesive palette." Layer gradients or geometric patterns rather than defaulting to solid colors. Allow asymmetry and overlap rather than asking for "good spacing." Each axis takes a single concrete commitment plus a prohibition list.
For brand mockup work, Anthropic recommends committing to a *bold aesthetic direction* up front rather than letting Claude explore freely. The frontend-design skill ships eleven directions to choose from: brutally minimal, maximalist chaos, retro-futuristic, organic / natural, luxury / refined, playful / toy-like, editorial / magazine, brutalist / raw, art deco / geometric, soft / pastel, industrial / utilitarian. The mechanism is *pick an extreme*. Moderate descriptions like "modern and clean" or "professional" describe the centre, which is the slop.
A what-works versus what-backfires cheat sheet, distilled from the community skills:
| Works | Backfires |
|---|---|
| Specific hex codes for primary and accent | Mood words alone ("modern, clean, professional") |
| Named fonts plus a "never use" list | "A nice sans-serif" |
| Reference URLs and screenshots in a `Reference/` folder | "Make it look like Stripe" without showing what about Stripe |
| A named aesthetic family (brutalist, editorial, RPG, solarpunk) | "Premium" or "high-end" |
| Quantitative spacing rules (padding ≥24px, max 3 font sizes) | "Good spacing" |
| Explicit "what NOT to do" list | "Be creative" |
| Single dominant color with a sharp accent | "Cohesive palette" |
Reference images help, especially when paired with detail. Pasquale Pillitteri's roundup of design skills suggests saving 2–3 screenshots from Mobbin, Dribbble, or Pinterest into a project `Reference/` folder, then asking Claude to analyse the visual reference and adapt the style. For Stitch, image inputs only work in Pro / Experimental mode (a forum gotcha worth knowing about), and the team's own guidance is that the image alone isn't enough; pair it with detailed text describing every detail you want preserved.
## Iterate one change at a time
The most reliably-reported failure mode in both tools is combining changes. The Stitch forum's canonical example is a user named `tempo`, who got a complex factory dashboard layout to land on a first prompt, then asked for filter dropdowns, title alignment, and an icon all at once. The next generation forgot everything and started over. The fix is the same in both tools: short, focused prompts; one change per iteration.
Where the workflows diverge is in *parallelism*. Claude Code rewards parallel exploration via subagents. The pattern from the `evanflow` skill collection (*design it twice; spawn three or more parallel sub-agents with radically different constraints; compare on depth, simplicity, efficiency*) works because the subtasks have no dependencies between them. Three radically different aesthetic directions, generated in parallel and compared, is faster and cheaper than three serial iterations of one direction.
Stitch's iteration is mostly serial, screen by screen, partly because of the credit system (the free tier is roughly 350 standard generations and 50–200 Pro generations per month) and partly because of the regeneration risk. The community guidance is to use Direct Edits and the Edit Theme panel (light/dark, accent color, corner radius, font swap) for everything that doesn't require a new generation, and to save screenshots after every successful iteration as a safety net. Stitch can reset unexpectedly; if you've been iterating for twenty minutes and lose the canvas, you can feed a screenshot back into Pro mode as a reference image and recover roughly where you were.
For closing the loop on Claude Code's own output, the Playwright MCP (installed with `claude mcp add playwright npx @playwright/mcp@latest`) lets the agent screenshot its own work, critique it against a reference, and propose adjustments. Julian Oczkowski's design-review skill describes catching "sparse layouts, incorrect chart ordering, missing dark mode considerations, and accessibility gaps" autonomously this way. The same loop is what closes the gap between "shipped a draft" and "shipped a draft that looks like the brand."
## The cross-tool primitive that won 2026: `DESIGN.md`
Originally introduced by Stitch and now open-sourced, `DESIGN.md` is a markdown file capturing color tokens, typography, spacing, radii, shadows, and component patterns for a brand. Stitch reads it before every generation. Claude Code skills read it as project context. Cursor, Gemini CLI, and the Antigravity IDE all read it too. One file, four agents.
You can write `DESIGN.md` by hand, generate it from your brand URL inside Stitch (Gemini analyses the rendered output and extracts a design system; Atal Upadhyay's hands-on review puts the extraction at roughly 80% accurate, so review and correct what comes out), or borrow one. The [VoltAgent/awesome-design-md repo](https://github.com/VoltAgent/awesome-design-md) curates ready-made files for Linear, Notion, Supabase, Resend, Cohere, and dozens of other brands you can use as templates.
The "one source of truth, two agents" workflow has become the canon. Generate or write `DESIGN.md` once. Drop it into your Claude Code project's `.claude/skills/` folder. Drop the same file into your Stitch project. Both tools then generate against the same tokens, and the post-generation drift between them is the smallest it's ever been. For a brand mockup specifically, this is the single most decisive piece of work you can do; almost everything else sits downstream of it.
## A drop-in `CLAUDE.md` for brand mockup work
Synthesised from the community templates. Under 200 lines on purpose. The *what NOT to do* section is doing most of the work:
```markdown
# Project: [Brand Name] Website
## Brand Voice
- Adjectives: [3–5 words]
- Says: [3 phrases the brand uses]
- Avoids: [3 phrases the brand never uses]
- Headline length: ≤8 words / ≤60 chars
## Design System
- Primary: #XXXXXX
- Accent: #XXXXXX
- Heading font: [name]; Body font: [name]
- Border radius: [values]
- Spacing scale: [values]; Min container padding: 24px
## Aesthetic Direction
- Pick one: editorial / brutalist / minimalist-warm / etc.
- Reference images in: ./Reference/
## Anti-Slop Rules
- Avoid Inter, Roboto, Open Sans, Space Grotesk
- Avoid purple-gradient on white
- No 3-up icon-card feature grids
- No hamburger nav on mobile
- Generate realistic copy, not Lorem Ipsum
- Maximum 3 font sizes per page
- Asymmetry and overlap preferred to grid-perfect layouts
```
The matching skills you want installed alongside it: Anthropic's own [`frontend-design` skill](https://github.com/anthropics/claude-code/tree/main/plugins/frontend-design) for aesthetic direction (reported at 277,000+ installs in third-party roundups as of March 2026), and [Vercel's `web-design-guidelines`](https://github.com/vercel-labs/agent-skills/blob/main/skills/web-design-guidelines/SKILL.md) as a quality gate that audits for accessibility and clarity.
## A starting prompt for Stitch
Stitch wants less than Claude Code does. Nick Babich's "Zoom-Out-Zoom-In" framework on UX Planet is the cleanest format I've seen. Context, then this specific screen's goal and hierarchy, then expectations:
```
Context: [Product] for [target user]. [One-line problem statement.]
Vibe: [3 adjectives, e.g. "warm, considered, restrained"].
Aesthetic boundary: [Material / neumorphic / editorial / brutalist / soft].
Screen: [name of this specific screen].
Goal: [what this screen helps the user do].
Hierarchy: [top-to-bottom or left-to-right structure in 4–6 items].
Specifics: [brand name, primary color description, font feel, button style].
Imagery: [one sentence on what the page should reflect visually].
```
Two notes from the forum that save credits. Click the edit button on a design first, then describe your changes; Stitch responds more reliably in edit mode than from the main prompt bar. And use the Edit Theme panel for light/dark, accent, corner radius, and font swap before regenerating. Those changes don't cost credits.
## Where each tool earns its keep
Claude Code generates real code with arbitrary motion, layout, and density. It rewards heavy upfront constraints in `CLAUDE.md` and skills, and parallel exploration via subagents. Use it when the deliverable is a working page, when you want motion or density that Material defaults won't reach, or when the brand has a strong existing identity you can encode precisely.
Stitch generates static screens with limited motion and Material-inflected defaults. It rewards lighter initial prompts plus iterative in-canvas refinement, and it shines when you're comparing layout variants quickly. Use it for early look-and-feel exploration, for screens you'll hand off to a designer in Figma, or as a first draft you'll bring into a coding agent for finishing.
KunalxArora's framing on Stitch holds for both: think of these as your first-draft generators, not your final brush. They build seventy per cent of the structure quickly, so you can spend your real attention on the refinement. Both still need an explicit anti-slop posture, an explicit voice, and a `DESIGN.md` they can read. Without those, you'll get the centre, every time.
---
## How to get Claude Opus 4.7 to write copy that doesn't sound like AI
URL: https://www.theadpharm.com/insights/claude-opus-anti-slop-playbook
Source markdown: https://www.theadpharm.com/insights/claude-opus-anti-slop-playbook.md
Published: 2026-04-03
Category: ai-and-tech
Author: adpharm-digital
Reviewed by: ben-honda
Tags: claude, prompting, copywriting, anti-slop, opus-4-7
> TL;DR: Don't put guardrails in every prompt: install them once in Custom Instructions or a Project. Paste 200–600 words of a chosen writer's prose, not just their name. Run three passes on every draft (write, critique, rewrite). Fix the negative-parallelism, tricolon, and em-dash trio first; it's most of the tell.
A tactical playbook for stopping Claude from sounding like a LinkedIn thought leader on espresso. Industry-agnostic, copy-paste, edit. The whole thing assumes you already know how to write; you just want the model to stop performing.
## Why Claude defaults to slop
Claude is not trying to sound like a tech-bro. It is a probability machine. Give it a vague brief and it lands on the statistical centre of all marketing prose ever scraped, which means LinkedIn, SaaS landing pages, and Medium thinkpieces. That centre is the slop.
Wikipedia's editors maintain a 15,000-word document called [*Signs of AI writing*](https://en.wikipedia.org/wiki/Wikipedia:Signs_of_AI_writing) cataloguing the tells. The [blader/humanizer](https://github.com/blader/humanizer) skill on GitHub (13.8k stars) distils it to twenty-nine patterns. Here is the short version of what actually trips the alarm:
**Vocabulary.** Delve, dive into, navigate (figurative), underscore, bolster, foster, harness, leverage, unpack, shed light on, pave the way. Pivotal, groundbreaking, cutting-edge, transformative, game-changing, innovative, robust, comprehensive, seamless, intricate, nuanced, multifaceted, holistic. Testament, landscape (figurative), realm, tapestry, ecosystem. Discover, Unlock, Elevate, Transform, Empower, Reimagine, Supercharge. The copula avoiders (*serves as*, *functions as*, *stands as*, *acts as*) used in place of plain *is*.
**Structure.** Negative parallelism ("It's not just X — it's Y"). Tricolons ("innovative, transformative, groundbreaking"). Mirror sentences ("The tool is a catalyst. The assistant is a partner. The system is a foundation."). Em dashes used for pseudo-emphasis where a comma would do. Bold-term-colon bullet lists where every item has the same shape. Setup-then-pivot openings ("In today's fast-paced world…"). Question-then-answer rhythm ("What does this mean? It means…"). Inflated symbolism via -ing analyses ("symbolising… reflecting… showcasing…").
**Tone.** Sycophantic preamble ("Great question!"). Wrap-up coda ("In conclusion, the future looks bright"). Promotional travel-brochure register ("nestled at the intersection of…"). Hedging stacks ("could potentially possibly"). Throat-clearing ("It's worth noting that…", "At its core…").
**Format, which Opus 4.7 still does without instruction.** Title Case Headings. Excessive bolding. Emoji headers. A three-bullet summary at the end of everything.
If you only fix one thing, fix the negative-parallelism, tricolon, and em-dash trio. Those three patterns alone produce roughly seventy per cent of the obvious tell.
## The single best leverage point
Do not put your guardrails in every prompt. Put them once, where Claude reads them automatically. There is a hierarchy:
| Layer | Where | What goes there |
|---|---|---|
| Global | Settings → Profile (Custom Instructions) | Banned-words list, voice defaults |
| Per-client | Projects → Project Knowledge + Custom Instructions | Brand voice doc, three to five writing samples, audience, tone rules |
| Per-task | Custom Style (Create & Edit Styles) | A specific stylistic preset, e.g. "Plain-spoken landing copy" |
| Per-message | Prompt | The brief: what, who, length |
In Opus 4.7 the Style feature is the one most people ignore. [Anthropic's own docs](https://docs.anthropic.com/en/docs/build-with-claude/prompt-engineering) confirm 4.7 needs less anti-slop scaffolding than 4.5 or 4.6, but only if it has something to anchor to. A Style with two pasted writing samples beats a 500-word prompt every time.
## The Custom Instructions block
Install once, in Settings → Profile or at the top of any Project. The shape, drawing on [Will Francis's widely-shared block](https://willfrancis.com/how-to-stop-claude-writing-like-an-ai/), the [blader/humanizer](https://github.com/blader/humanizer) pattern list, and [lguz/humanize-writing-skill](https://github.com/lguz/humanize-writing-skill):
A working block lives at six layers — voice defaults, banned words, banned phrases, banned structures, punctuation and format rules, prose discipline, plus a self-check Claude runs before returning. The vocabulary list runs to about thirty-five words. The structures list bans the five patterns flagged above (negative parallelism, three-fragment kickers, mirror sentences, question-then-answer rhythm, three-item lists where two would do). The self-check forces a read-aloud, a setup-sentence delete, a summary-sentence delete, and an em-dash count before the response leaves the model.
The exact block is something we maintain per client and don't publish. The leverage point isn't the wording — it's the architecture: write it once, install it once at the right layer, stop pasting guardrails into every prompt. Done well, the block alone removes about eighty per cent of the obvious slop. The remaining twenty per cent is voice.
## Pick a copywriter and paste their prose
Naming a copywriter in the prompt nudges Claude, but vaguely. Naming a copywriter and pasting 200–600 words of their actual prose is what shifts the output. Opus 4.7 does style transfer well from samples and badly from names alone.
A short list of distinguished references that produce a clear style shift in testing:
| Reference | What it gives you | Use when you want |
|---|---|---|
| **David Ogilvy** (*Ogilvy on Advertising*, the Rolls-Royce ad) | Confident specifics, factual claims, no fluff | Authoritative, considered B2B or premium consumer |
| **Bill Bernbach** (VW "Think Small," Avis "We Try Harder") | Wit, self-deprecation, brevity, respect for the reader | Brands that want charm and an underdog stance |
| **Dave Trott** (*Predatory Thinking*) | Punchy short paragraphs, plain English, story-led | Editorial brand writing without sounding "punchy AI" |
| **Joe Sugarman** (*The Adweek Copywriting Handbook*) | Slippery-slide rhythm, conversational | Long-form sales pages, founder letters |
| **Ann Handley** (*Everybody Writes*) | Warm, plain, useful, lightly literary | Content marketing that isn't "content marketing" |
| **George Orwell** ("Politics and the English Language") | Plain words, active verbs, no ornament | Anything where you want the model to tighten up |
The Orwell trick is worth its own line. Paste this into your system prompt:
> *Apply Orwell's six rules from "Politics and the English Language." Especially: never use a long word where a short one will do; if it is possible to cut a word out, cut it out; never use the passive where you can use the active.*
The output tightens noticeably. Citing the essay is the cheapest single intervention in this whole playbook.
## The three-sample rule
Naming a writer does about ten per cent of the work. Pasting samples does the other ninety.
The mechanism: drop three short passages of the target voice (150–300 words each) into a Project or Style, tell Claude to study them for sentence-length variance, word choice, what the writer refuses to say, where they break rhythm, where they use specifics instead of abstractions, default verb tense, and first-person use. Tell it explicitly to imitate the voice, not the topic. Then — and this is the part that matters — *make it list the five voice characteristics it observed before drafting a single word*.
That "list five first" step is the active ingredient. It forces Claude to extract the style explicitly instead of regressing to its mean. Skip it and you lose about half the gain.
## Words to remove from your own prompt
These are the things people put in briefs that reliably degrade the output. Strike them:
- *Engaging.* Pulls Claude toward exclamation-marked enthusiasm.
- *Compelling.* Triggers superlative stacking.
- *Punchy.* Triggers fragment-spam and three-word sentences.
- *Modern, fresh, dynamic.* Activates the SaaS-landing-page register.
- *Concise but powerful.* Produces gnomic Yoda-LinkedIn.
- *Use vivid imagery.* Triggers metaphor inflation.
- *Optimised for conversion.* Generic AIDA bilge.
- *Professional yet approachable.* The most AI-coded phrase of all; produces the exact register you're trying to avoid.
- *Add some personality.* Triggers forced quirkiness.
- Em dashes in your own prompt. Claude mirrors your punctuation.
Replace each with a concrete constraint:
- Instead of "engaging," write "the reader should want to read sentence two after reading sentence one."
- Instead of "punchy," write "average sentence length 14 words; vary between 4 and 28."
- Instead of "professional yet approachable," write "the way [specific writer] writes; see samples."
- Instead of "compelling," write "include one specific number, one named thing, and one concession."
## The three-pass workflow
A single prompt cannot fix slop. The pros run three passes, each with one job — the structure used by both [blader/humanizer](https://github.com/blader/humanizer) and [lguz/humanize-writing-skill](https://github.com/lguz/humanize-writing-skill), and by every working agency workflow.
**Pass 1. Draft, do not optimise.** Hand Claude the brief — page type, brand, reader, the reader's situation, the action you want, length, must-mention facts, voice samples — and tell it explicitly not to self-edit, not to add a conclusion, not to apologise, and to stop when the idea stops.
**Pass 2. Critique. Claude finds its own slop.** This is the pass most teams skip and the one that does the most work. Tell Claude to read the draft as a hostile editor and produce a numbered list of every instance of: negative parallelism, tricolons and three-adjective stacks, em-dash count, banned vocabulary, opener tells ("In today's…", "Imagine…", "Whether you're…"), copula avoidance, bold-term-colon bullets, wrap-up codas in the final paragraph, sentences that could be cut entirely without losing meaning, and abstractions a specific noun or number could replace. Each offender quoted verbatim. No rewriting yet.
**Pass 3. Rewrite against the critique.** Hand Claude its own critique back with hard constraints — replace at least three abstractions with specific nouns or numbers, include at least one sentence under six words and one over twenty-five, cut the opening if it's setup, cut the closing if it's a summary, keep the meaning, don't soften the claims, return only the rewritten copy.
The three-pass loop, run inside one Claude conversation, is the difference between "AI draft I have to fix" and "draft I'd put my name on with a light edit." It costs about three times the tokens. Worth it.
The faster alternative is to install the [blader/humanizer](https://github.com/blader/humanizer) skill in Claude.ai (Customize → Skills → Upload, point at the GitHub zip), then end any prompt with `use the humanizer skill`. You get pass 2 and pass 3 free.
## The template that earns its keep
Eight templates is too many to remember. The one that earns its keep names a specific writer, summarises their voice in a single sentence (short paragraphs, plain English, one idea per paragraph, anecdote-led, no adjectives where a verb will do — whatever applies), and asks Claude to *list five things that writer would NOT do that a typical SaaS landing page does* before handing over the brief, length, and must-include facts.
Swap Trott for Bernbach, Ogilvy, Sugarman, Wiebe, Handley as the brief calls for. The "list five things they would NOT do first" step is the active ingredient — same mechanism as the three-sample rule, applied to a single named writer.
## Holding the voice over a long session
Even with all the above, Claude drifts back toward its default register over a long session. Three techniques hold the line. First, re-anchor every four or five turns by pasting a reference sample again with the instruction *recalibrate; the voice should match this sample, not the previous outputs; identify three ways the last response drifted, then redo it*. Second, run the two-voice test: ask Claude to write the same paragraph twice, once in the brand voice and once in default Claude voice, then list every difference. It forces the model to notice and protect the voice in subsequent turns. Third, repeat critical rules as the last line of the prompt, not buried in the system prompt; the position weights more there.
## Before and after, so you can see it
**Brief.** Hero copy for a project management tool aimed at small agency owners.
**Default Claude Opus 4.7, no instructions:**
> ### Reimagine How Your Agency Delivers
> The all-in-one platform that empowers creative teams to streamline workflows, foster collaboration, and deliver standout work — every time. It's not just project management; it's the operating system your agency has been waiting for.
>
> **Get Started Free**
**Same model, with the Custom Instructions block, a Trott-style anchor, and the three-pass workflow:**
> ### Your projects don't run late. Your replies do.
> Most agency tools track tasks. This one tracks the bottleneck — the email you owe a client, the brief still sitting in your drafts, the approval nobody's chased. Six agencies tested it for ninety days. Average reply time fell from 31 hours to 4.
>
> **Try it on one project**
Same product. Same model. Different scaffolding. The second one wouldn't embarrass you.
## A note on detection scores
Most of this is stable: the Wikipedia [*Signs of AI writing*](https://en.wikipedia.org/wiki/Wikipedia:Signs_of_AI_writing) taxonomy, the [blader/humanizer](https://github.com/blader/humanizer) pattern list, Anthropic's own [prompt-engineering docs](https://docs.anthropic.com/en/docs/build-with-claude/prompt-engineering) (which now mention the AI slop aesthetic by name and confirm Opus 4.7 needs less anti-slop scaffolding than 4.5 or 4.6, but still benefits from style anchors). Skills, Projects, and Styles are documented features in claude.ai today.
What is contested is detection. Multiple humaniser-tool vendors claim their output bypasses [GPTZero](https://gptzero.me) and [Originality](https://originality.ai); independent tests put Claude's own self-rewrite at around 48% AI on [GPTZero](https://gptzero.me)[^claude-self-rewrite]. If your goal is evading detection, the prompting techniques here are not sufficient on their own. If your goal is not embarrassing yourself in front of clients who know good copy, they are more than enough.
Bookmark the page, paste the Custom Instructions block once, and come back when output starts drifting.
[^claude-self-rewrite]: Independent comparison reported in *Can Claude Humanize Text? We Tested Anthropic's AI Against 3 Detectors*, [thehumanizeai.pro](https://thehumanizeai.pro/articles/can-claude-humanize-text). Claude's best self-rewrite scored 48% AI on GPTZero (compared to ChatGPT's best of 61%); both are still failing scores by GPTZero's threshold.
---
## Google's 2025 HCP targeting changes, read for Canadian pharma
URL: https://www.theadpharm.com/insights/google-hcp-targeting-2025-policy-change
Source markdown: https://www.theadpharm.com/insights/google-hcp-targeting-2025-policy-change.md
Published: 2025-11-05
Category: compliance
Author: the-adpharm
Reviewed by: ben-honda
Tags: google-ads, hcp-marketing, paab, health-canada, canadian-pharma, personalised-advertising, restricted-drug-terms, customer-match
> TL;DR: Google rewrote its rules on personalised advertising to healthcare professionals across three dated steps in 2025: May 29 (announcement), July 1 (Restricted Drug Terms exclusion takes effect), October 29 (enforcement of a new prescription-drug certification in Canada, the United States, and New Zealand). For Canadian pharma, this opens Customer Match, Remarketing, and Similar Audiences against HCP lists. The Food and Drugs Act, PAAB, and the Innovative Medicines Canada code did not change.
The 2025 changes to Google's HCP advertising policy came in three steps, across two policy documents. The summer-2025 shorthand is broadly correct: pharma can now use personalised audiences to reach physicians on Google. What's underneath that headline determines whether a Canadian campaign clears review at the platform, at PAAB, and under the Food and Drugs Act.
## The three-step 2025 timeline
The change touches the **Personalized advertising policy** (which governs how audiences can be assembled) and the **Healthcare and Medicines policy** (which governs what can appear in ads). Three dates:
| Date | Document | What changed |
|---|---|---|
| **May 29, 2025** | Personalized advertising policy | Health sensitive interest category clarified to exclude "content directed at healthcare professionals in their professional capacity". Effective immediately. |
| **July 1, 2025** | Personalized advertising policy | Restricted Drug Terms sensitive interest category updated to carry the same HCP exclusion. Effective on this date. |
| **October 29, 2025** | Healthcare and Medicines policy | Enforcement begins on a new certification for advertisers using prescription drug terms in ads, landing pages, or keywords. Canada is one of three markets in scope (alongside the United States and New Zealand). |
The May 29 notice is the source document. Posted at [support.google.com/adspolicy/answer/16258024](https://support.google.com/adspolicy/answer/16258024), it reads:
> The Health sensitive interest category has been updated to clarify the exclusion of "content directed at healthcare professionals in their professional capacity."
>
> The Restricted Drug Terms sensitive interest category will be updated to exclude "content directed to healthcare professionals in their professional medical capacity." Effective: July 1, 2025.
Everything downstream (the certification, the agency letter, the October enforcement schedule) follows from those two paragraphs.
## What was off-limits before
Until May, Google treated the audience itself as sensitive. Any "Health" interest signal, and any "Restricted Drug Terms" signal, was excluded from personalised targeting across the board. For Canadian pharma, the practical consequences:
- Customer Match against a list built from the Canadian Medical Association's physician database, provincial licence rolls, or an IQVIA dataset was not permitted. The list was treated as health-sensitive and refused for personalised serving.
- Remarketing on HCP-facing properties was off the table. A visitor to a branded prescriber portal or a Canadian HCP product site could not be re-engaged with a personalised follow-up creative.
- Similar Audiences modelled against an HCP seed was excluded for the same reason: the seed list was sensitive, so the lookalike was off-limits.
- Interest-category overlay on prescription drug terms was not available, even where the keyword itself was permitted.
Canadian pharma media buyers running professional-audience campaigns spent on contextual signals (publication, query, page) and gave up the personalised-audience layer. The Canadian endemic HCP environments (CMAJ, the EnsembleIQ healthcare titles, Medscape Canada) absorbed the budget that Google would not take.
## What is now permitted
After July 1, 2025, the following are allowed when the audience is licensed Canadian healthcare professionals in their professional capacity:
- Customer Match against HCP lists. Customer Match accepts hashed email addresses, phone numbers, and mailing addresses; the credentialling step is the source list. CMA-derived physician data, provincial licence-derived lists (CPSO, CPSBC, CPSA, and the equivalents), and IQVIA or comparable datasets are the standard inputs.
- Remarketing to visitors of HCP-gated properties: branded prescriber portals, MSL request pages, sample-request flows, professional registration journeys.
- Lookalike or Similar Audiences modelled from HCP seeds.
- Interest- and affinity-category targeting that overlays Health signals on professional-audience campaigns.
- Restricted Drug Terms as keyword and ad-copy elements in prescription-targeted campaigns, subject to the certification described in the next section.
The phrase that does the work is *in their professional capacity*. Google's stated rationale, surfaced in industry coverage, is that an HCP receiving information about a prescription product as part of their work is not the end consumer of that product. The privacy logic that drove the original sensitive-category exclusions (HIPAA in the United States, PIPEDA and provincial overlays in Canada) does not apply in the same way when the audience is a prescriber reviewing therapeutic options rather than a patient researching a condition.
That distinction is the load-bearing assumption of the policy change.
## The certification gate
The October step is the one that requires operational work. The Healthcare and Medicines policy update covers advertisers in **Canada, the United States, and New Zealand** who plan to use prescription drug terms anywhere in the campaign: ad copy, landing page, or keyword list.
What a Canadian advertiser has to do:
1. Apply for a Healthcare and Medicines certification through the advertiser portal.
2. Attest to compliance with applicable federal, provincial, and self-regulatory standards. In Canada that is the Food and Drugs Act and its regulations, PAAB pre-clearance for branded HCP-facing creative, and (for Innovative Medicines Canada members) the IMC Code of Ethical Practices.
3. Where an agency is running the campaign on behalf of a healthcare organisation, submit a letter of authorisation from that organisation. Industry coverage from agencies that have gone through the process describes a Google-supplied LOA template, signed by the manufacturer's regulatory or marketing lead and uploaded by the agency as a PDF. The template is not published on Google's policy page; the route in is via the certification application itself or the Google Ads account team.
4. Submit the marketing information (customer lists, websites, advertisements) for compliance verification before the personalised tools unlock.
Industry reporting describes a four-to-six-week ramp on enforcement and a seven-day warning before account-level suspension. Markets outside the Canada, US, and New Zealand scope are not part of the certification path, because Google's underlying policy on prescription drug promotion in those markets remains generally prohibited, with narrow exemptions for non-promotional uses (public health notices, academic research). The 2025 change is regional, sitting on top of local pharma-advertising regimes.
## What did not change
A few things often get rolled into the summary that the policy did not actually touch.
Consumer-directed prescription drug rules in Canada are unchanged. Section C.01.044 of the Food and Drug Regulations still limits consumer-facing advertising of prescription drugs to the drug's name(s), price, and quantity. Reminder ads (under C.01.044) and help-seeking messages (under Health Canada's Distinction Between Advertising and Other Activities guidance) sit in different regulatory frameworks but are both unchanged by the 2025 Google policy update.
PAAB review is unchanged. Branded HCP communication for prescription drugs in Canada still goes through PAAB, the only pre-clearance service Health Canada recognises for HCP-directed health product advertising. The Google certification is a platform-level layer that sits on top of, not in place of, the PAAB Code of Advertising Acceptance and the medical and regulatory review the brand team already runs.
The Innovative Medicines Canada code is unchanged. IMC member companies still follow the IMC Code of Ethical Practices on HCP interactions and marketing materials. The 2025 Google change does not loosen any provision of the IMC code; if anything, it puts more pressure on the code's interpretation in digital channels because the targetable surface area just expanded.
PIPEDA and provincial privacy rules are unchanged. The federal privacy framework, plus provincial overlays (Quebec's Law 25, Ontario's PHIPA in clinical contexts, British Columbia's PIPA, Alberta's PIPA), still govern collection, use, and disclosure of personal information used to build HCP lists. The 2025 change addresses one specific exclusion in personalised audience eligibility; it does not change the consent and notification obligations for assembling the audience in the first place.
What can be claimed in ad copy is unchanged. Restricted Drug Terms certification permits use of the term in keywords, copy, and landing pages where local law allows. It does not change which claims are allowable under PAAB or under the Food and Drugs Act.
The role of endemic Canadian HCP networks is unchanged in kind. CMAJ, the EnsembleIQ healthcare titles (the Medical Post, Pharmacy Practice+, Profession Santé for French-speaking HCPs), Medscape Canada, and similar inventory still hold the credentialled, peer-network, clinical-context advantages they have always had. The 2025 change makes Google a viable second lane, not a replacement.
## Things to verify before launch
A short list, weighted toward the things that trip Canadian campaigns at platform review:
1. The Customer Match audience must be HCP-credentialed, not a consumer list with a healthcare interest signal. Document the provenance: CMA Masterfile derivation, provincial licence roll, IQVIA Brogan output, or a similar credentialled source.
2. PAAB pre-clearance is the long pole on creative. Schedule it ahead of the Google certification, not in parallel; Google will ask for the marketing information and the cleanest version is the PAAB-cleared version.
3. The Google certification application takes weeks to clear, not days. If a launch is on the calendar, it is the long pole on platform.
4. Agencies need the LOA signed by the manufacturer's regulatory or marketing lead before submission. Most delays here are signature-routing, not policy.
5. Quebec language requirements apply. The Charter of the French Language, as amended by Bill 96, requires French in commercial advertising in Quebec, including digital ads served to Quebec audiences. The compliance deadline for the digital-presence rules was June 1, 2025; penalties run from $3,000 to $30,000 per violation. Plan a French version of any creative that will run with provincial reach, and document the version control.
6. Privacy obligations clear separately from the platform certification. Confirm PIPEDA-compliant consent for any list source that originated from a non-public dataset; in Quebec, confirm Law 25 obligations for the assembly and use of the list.
7. The May 29, 2025 personalised-advertising notice and the current Healthcare and Medicines policy are the authoritative platform-side documents. Industry summaries (this one included) compress and paraphrase.
## What this means for media planning
The substantive consequence for Canadian pharma is that media buyers can now run an HCP audience strategy on the same platform stack that runs the rest of the digital programme: Customer Match against a CMA-derived list, Remarketing on a branded HCP portal, Similar Audiences modelling, YouTube reservations against the same audience seeds. Google sits in direct comparison with the Canadian endemic HCP environments for budget that previously had nowhere else to go.
The questions that follow are not policy questions. They are media-planning questions: which performance signals translate cleanly between an EnsembleIQ placement and a Google Customer Match campaign, how attribution settles between a branded HCP portal visit and a Search conversion, what kind of frequency capping survives the move from credentialled environments to general-purpose ad infrastructure. Those belong in a strategy piece.
For the policy itself, what matters is the three dates. May 29, July 1, October 29.
## Source documents and further reading
- Google Ads — [Update to the Personalized advertising policy (May 2025)](https://support.google.com/adspolicy/answer/16258024)
- Google Ads — [Update to Healthcare and Medicines Policy (July 2025)](https://support.google.com/adspolicy/answer/16328091)
- Justice Canada — [Food and Drug Regulations, Section C.01.044](https://laws-lois.justice.gc.ca/eng/regulations/c.r.c.,_c._870/page-51.html)
- Health Canada — [Illegal marketing of prescription drugs](https://www.canada.ca/en/health-canada/services/drugs-health-products/marketing-drugs-devices/illegal-marketing/prescription-drugs.html)
- Health Canada — [Guidance on the distinction between advertising and other activities for health products](https://www.canada.ca/en/health-canada/services/drugs-health-products/regulatory-requirements-advertising/policies-guidance-documents/policy-distinction-between-advertising-activities.html)
- Pharmaceutical Advertising Advisory Board — [PAAB Code of Advertising Acceptance](https://code.paab.ca/)
- Innovative Medicines Canada — [2022 Code of Ethical Practices](https://innovativemedicines.ca/resources/all-resources/2022-code-of-ethical-practices/)
- Office of the Privacy Commissioner of Canada — PIPEDA guidance on consent and personal information in marketing
- Accelerated Digital Media — [Google Ads Policy Changes Allow Health Brands to Target Healthcare Professionals](https://www.accelerateddigitalmedia.com/insights/google-health-advertising-update-july-2025/)
- Odyssey New Media — [Google's New Certification for Prescription Drug Advertising](https://www.odysseynewmedia.com/2025/10/googles-new-certification-for-prescription-drug-advertising/)
---